Written by: Anish Rao, Head of Growth, Listen Labs
Key Takeaways
- Brand tracking often misses niche segments because of three design failures: sample size, sourcing bias, and locked question sets that exclude community vocabulary.
- General-population panels systematically under-represent low-incidence audiences, and weighting cannot correct for respondents who never join panels in the first place.
- Demographic cuts slice averages and do not capture communities defined by identity, interest, or usage occasion that actually drive behavior.
- Closed-ended trackers record metric movement but cannot explain why it happened, leaving teams with numbers and no diagnosis.
- Listen Labs solves all three layers at once with Listen Pulse while preserving the KPIs and trend line teams already report.
Why Brand Tracking Misses Niche Segments: Four Failure Modes
Brand trackers miss niche segments for specific, repeatable reasons. Each failure mode below explains the mechanism, shows a concrete example, and offers a design fix.
1. The Incidence-Rate Arithmetic
A segment with 1% incidence in a 1,000-person general-population sample yields roughly 10 respondents. Trends from that tiny base blur into noise.
The mechanism is straightforward: margin of error scales with the square root of sample size. Cochran’s formula, n = (Z² × p × (1−p)) / E², shows that at 95% confidence and ±5% margin of error, the required sample is approximately 385 respondents for a total-level estimate. That precision does not carry over to small subgroups. A subgroup of 50 carries a margin of error of roughly ±14%, which rarely supports confident decisions. A subgroup of 10 is not a sample; it is anecdote.
Sapio Research’s methodology guidance is explicit that the minimum sample threshold applies to each subgroup individually, not to the total sample. For meaningful comparisons between groups, 100 or more respondents per subgroup is the recommended floor.
Worked example: a segment with 1% incidence in a 1,000-person sample produces approximately 10 respondents. No weighting scheme recovers statistical reliability from that base. The small-sample problem arises from design choices, not from budget alone.
Design fix: size each subgroup to the target precision separately, rather than to the total sample. When a subgroup is the unit of decision, it needs its own adequate base.
Even with correct subgroup sizing, the way respondents are sourced can still hide niche audiences. That sourcing problem creates the second failure mode.
2. General-Population Panel Bias
Niche buyers are structurally absent from mainstream panels. Panel composition skews toward heavy survey-takers, and low-incidence audiences are expensive and slow to source, so they often get dropped or under-filled.
The mechanism is panel conditioning: repeated participation changes how people answer. The US Current Population Survey documented 7.5% unemployment among first-time respondents versus 6.1% among eighth-time respondents in the same months of 2014, using samples designed to be equally representative. This gap shows that the most responsive, articulate panel members differ systematically from the target population.
The problem extends beyond conditioning. Access panel participants tend to be more interested in the topic and less open-minded than the general public. When a panel under-represents people who avoid online research entirely, demographic weighting cannot fully compensate.
A panel database may show several hundred records matching a specialist profile. In practice, between stale profiles, misrepresented credentials, and chronic respondents, the real usable sample is often only a fraction of what the counts suggest. A general consumer study might see an incidence rate above 60%, while a study targeting a single medical specialty treating a rare condition can fall below 2%. General panels are not built to bridge that gap.
Design fix: source respondents where the community actually is, rather than from a general-population frame. Specialist recruitment via professional associations, specialist societies, and curated network lists produces substantially better data than panel databases.
Even with better sourcing, many trackers still slice the data in ways that flatten real communities. That slicing problem drives the third failure mode.
3. Demographic Cuts Versus Identity- And Interest-Based Communities
Demographic segmentation slices the average and misses communities defined by identity, interest, or usage occasion.
Demographic similarity does not predict behavioral similarity. Two people with identical demographic profiles can hold entirely different values, cultural references, and purchasing motivations. According to Nielsen Digital Ad Ratings, 63% of digital ad impressions reach the wrong demographic target. That statistic shows how weak demographic categories are as proxies for behavioral clusters.
A 28–40 urban professional bracket contains hardcore runners, people in a first pregnancy, small business owners, and vintage fashion enthusiasts. These are communities with entirely different vocabularies, media habits, and values, so a message calibrated to their demographic average speaks to none of them. Traditional segmentation imposes categories defined before data collection, while community-based research discovers segments that emerge from observed behavior. Discovered segments tend to be more stable and more actionable.
Design fix: discover segments from observed behavior and community membership rather than imposing categories before data collection. Demographics answer who someone is on paper, while community-based methods capture what people care about and how they actually cluster.
Even with the right segments, many trackers still rely on rigid question sets that cannot capture how those communities talk. That rigidity creates the fourth failure mode.
4. Closed-Ended, Wave-Consistent Question Design
Locked question sets lock out the vocabulary, category entry points, and usage occasions that define a niche community. Respondents answer in the tracker’s language instead of their own.
A fixed response list only reflects what the researcher already thought to include, so genuinely new categories, explanations, or concerns go unrecorded. Wave-to-wave comparability requires identical wording, which keeps niche vocabulary out of the question set permanently. A tracker’s entire value comes from wave-to-wave comparability. That value explains why Listen Pulse keeps core questions constant wave over wave while timely add-on questions cover new campaigns, competitors, or news events without breaking historical comparability.
A tracker can show that consideration dropped 3 points among a segment but cannot reveal that a viral post reframed the brand’s messaging as performative, spread through communities the brand team was not monitoring. The closed-ended format records the metric movement and has no mechanism for recording the cause.
Design fix: layer open-ended conversational tracking onto the existing KPI framework so every metric movement arrives with its explanation in the same wave, while core questions stay constant.
How Standard KPIs Misread Niche Brands
Standard awareness and favorability KPIs often understate the strength of niche brands with intense community loyalty.
A niche brand can have high advocacy and low mass awareness, and a general-population awareness KPI reads that pattern as weakness. The KPI framework itself understates the segment. Two brands with identical aided awareness can differ dramatically in purchase outcomes depending on how many category entry points they are linked to. The Ehrenberg-Bass Institute’s empirical work across categories consistently shows that the number of category entry points linked to a brand is a stronger predictor of market share than awareness, consideration, or even purchase intent scores. As they put it, “awareness without context is a number on a slide.”
A niche brand with intense loyalty inside a small community scores poorly on mass awareness while its actual buyers think of it in more buying situations than a higher-awareness competitor. The blended score hides both the strength and the strategic opportunity.
Design fix: measure mental availability and category entry point ownership alongside awareness, and cut language by segment rather than reporting a blended score.
These four failure modes share a common root: a measurement design that treats the general population as the main unit of analysis. The solution keeps the tracker but redesigns it so niche segments become visible without breaking the trend line.
See How Listen Pulse Runs A Segment-Valid Tracker
The Fix: A Segment-Valid Tracker That Keeps Your Trend Line
The fix comes from measurement design rather than from adding more qualitative projects. Three moves address the failure modes above while preserving the trend line.
Oversampling The Niche Segment
Oversampling in brand tracking means deliberately collecting more responses from a specific subgroup than its population proportion would naturally produce, then applying post-stratification weights to restore correct population proportions. If a subgroup is 5% of the population and you need 200 completed interviews, a proportionate sample would require 4,000 total completes, but oversampling at a 4:1 ratio yields the 200 target interviews within a total sample of roughly 1,600. The trade-off is real: every oversampling scheme increases the design effect, so total-level precision narrows. That trade-off is worth accepting when the subgroup is the unit of decision.
Community-Native Recruitment
Source participants where the community actually is, including hard-to-reach and below-1%-incidence audiences. General panels “simply do not have the penetration you need” for hard-to-reach audiences. Specialist recruitment through professional associations, specialist societies, and curated network lists produces substantially better data for brand tracking niche audiences than panel databases. The improvement starts in the screening stage, before a single substantive question is asked.
Open-Ended Conversational Tracking Layered Onto Existing KPIs
Keep core questions constant to protect the trend line, and add open-ended conversation to every wave so the metric change and the reason behind it arrive together. Wave-to-wave comparability is the tracker’s core value, which is why the qualitative layer must sit alongside the locked core rather than replacing it. The conversational layer explains the trend line while the closed-ended metrics stay intact.
How Listen Pulse Runs A Segment-Valid Tracker
Listen Pulse is the conversational tracker from Listen Labs. It runs the same study with the same screeners wave after wave, understands open-ended answers, sorts them into themes, quantifies them, and charts each theme next to the KPIs teams already report. It deploys alongside an existing tracker or as the primary tracking system and integrates with Qualtrics and Decipher, so teams keep the KPIs they already report while adding the narrative behind them.
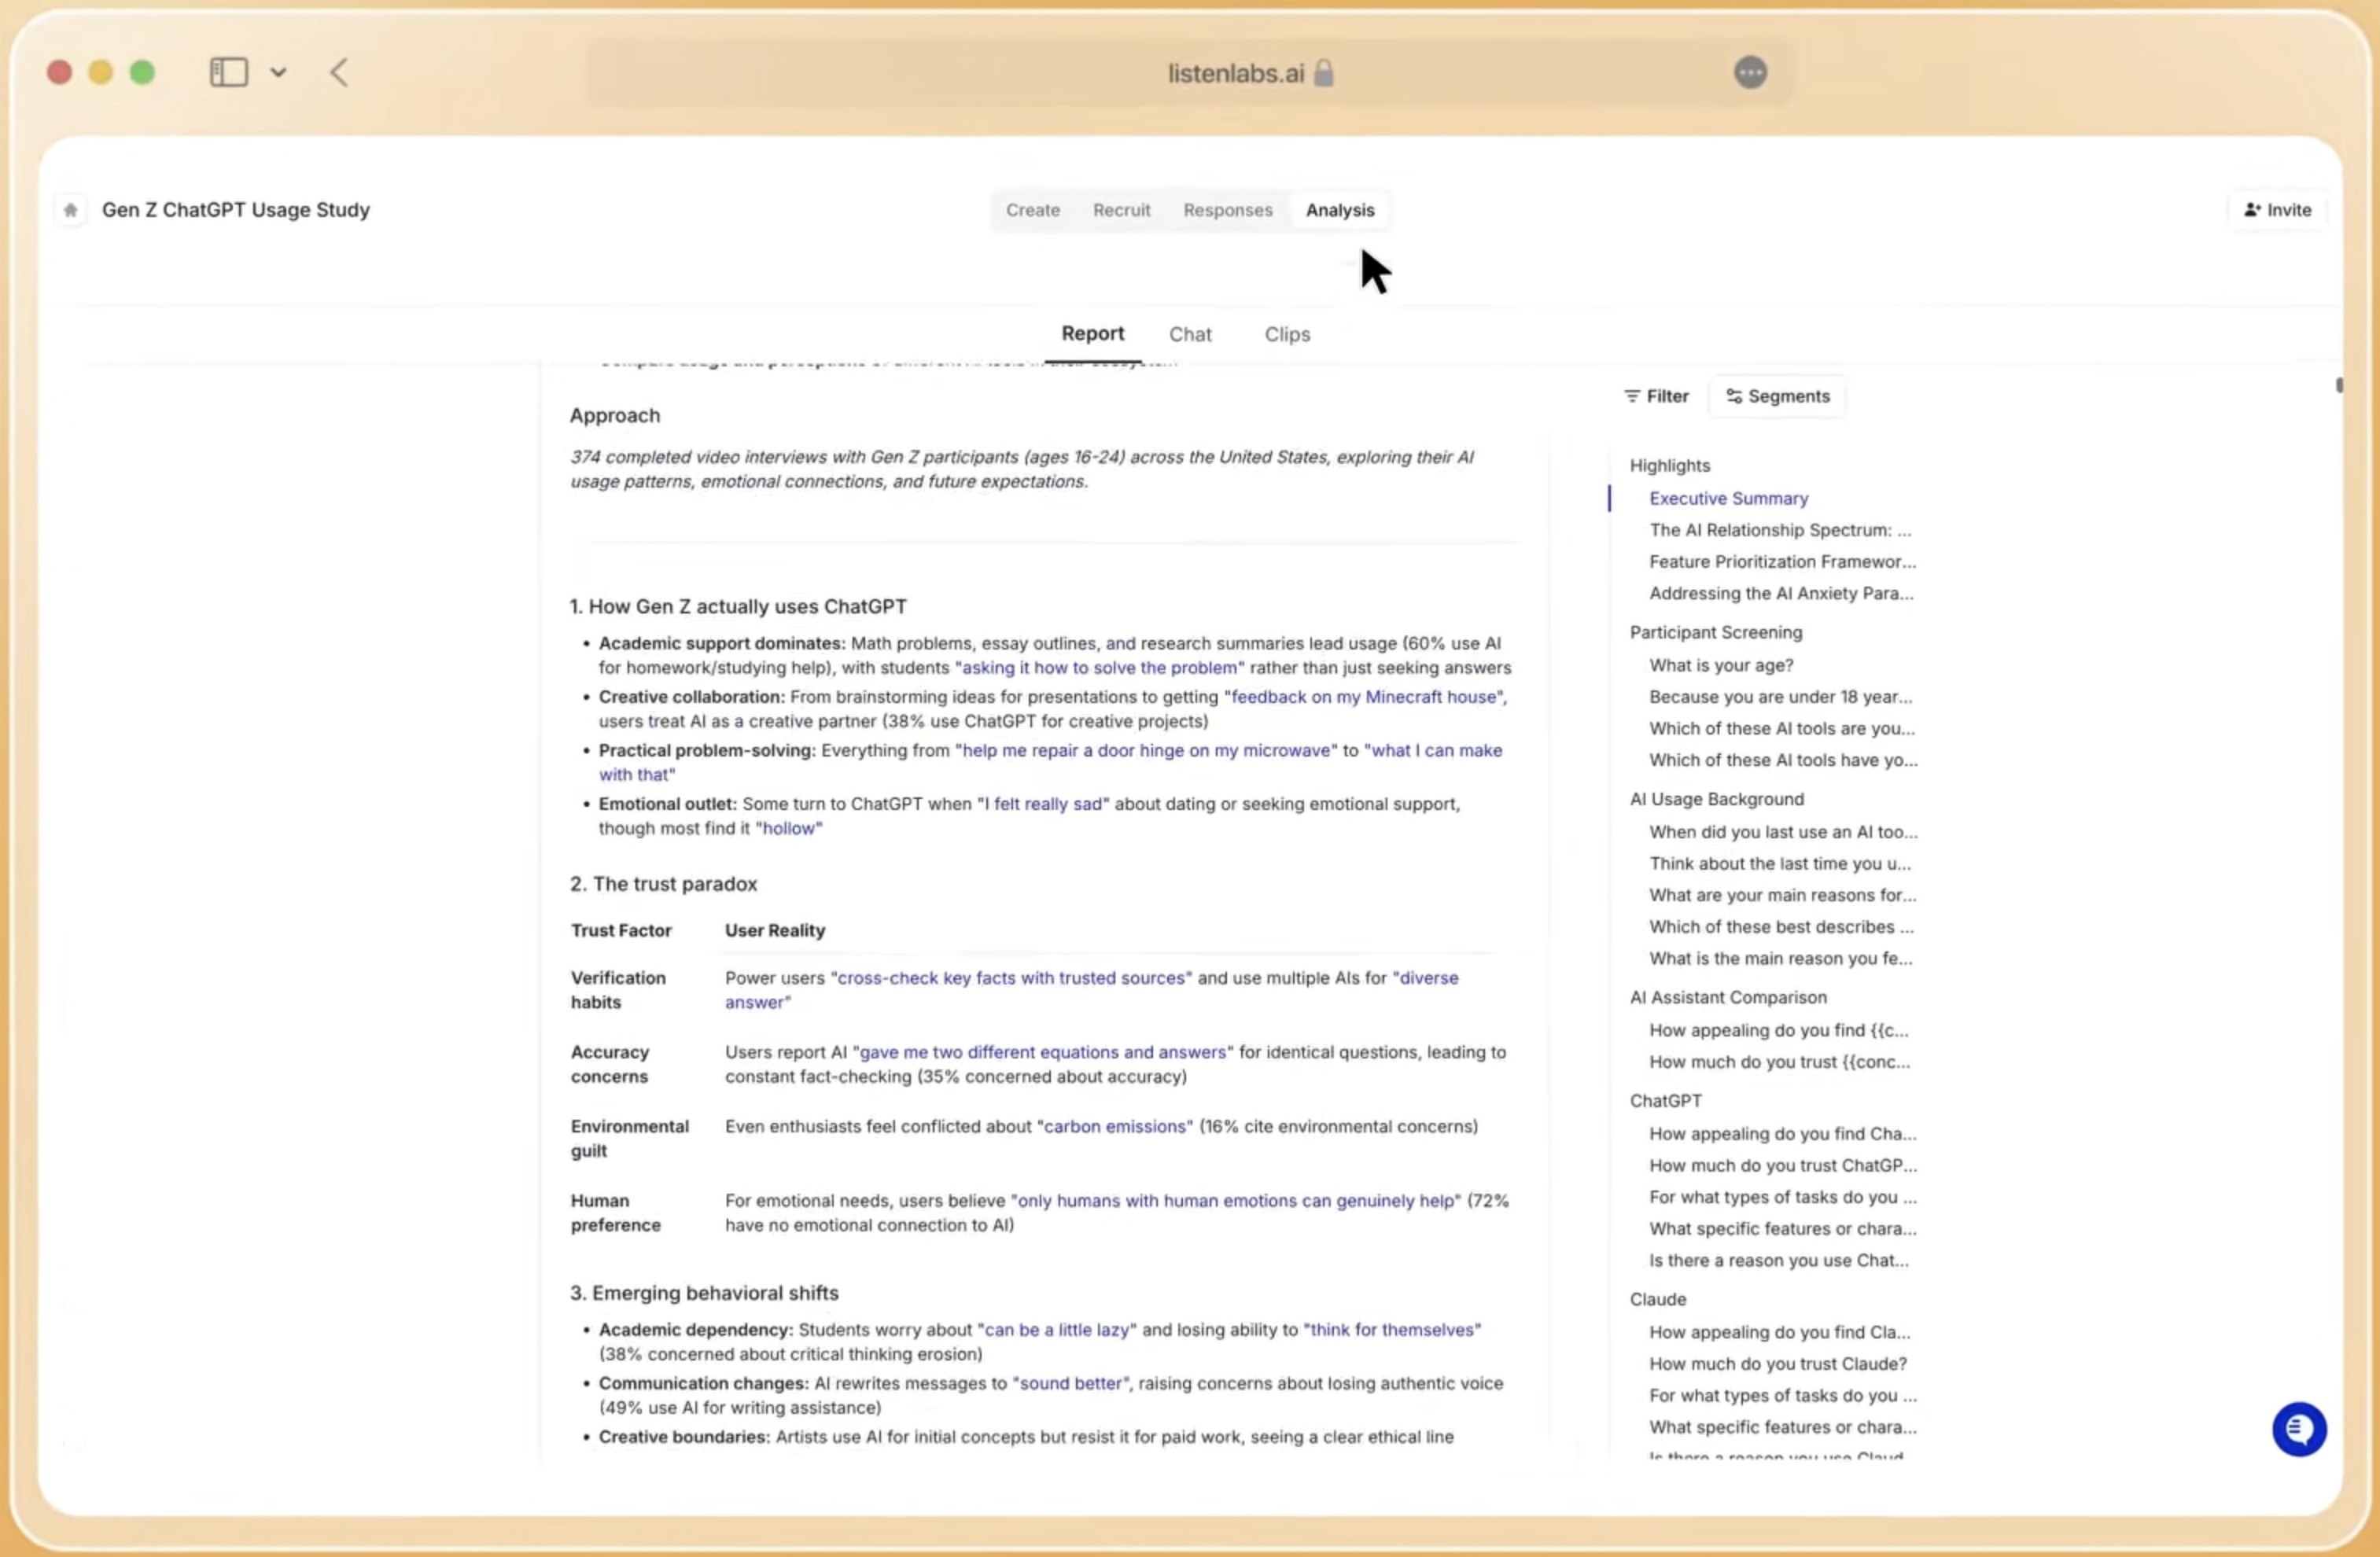
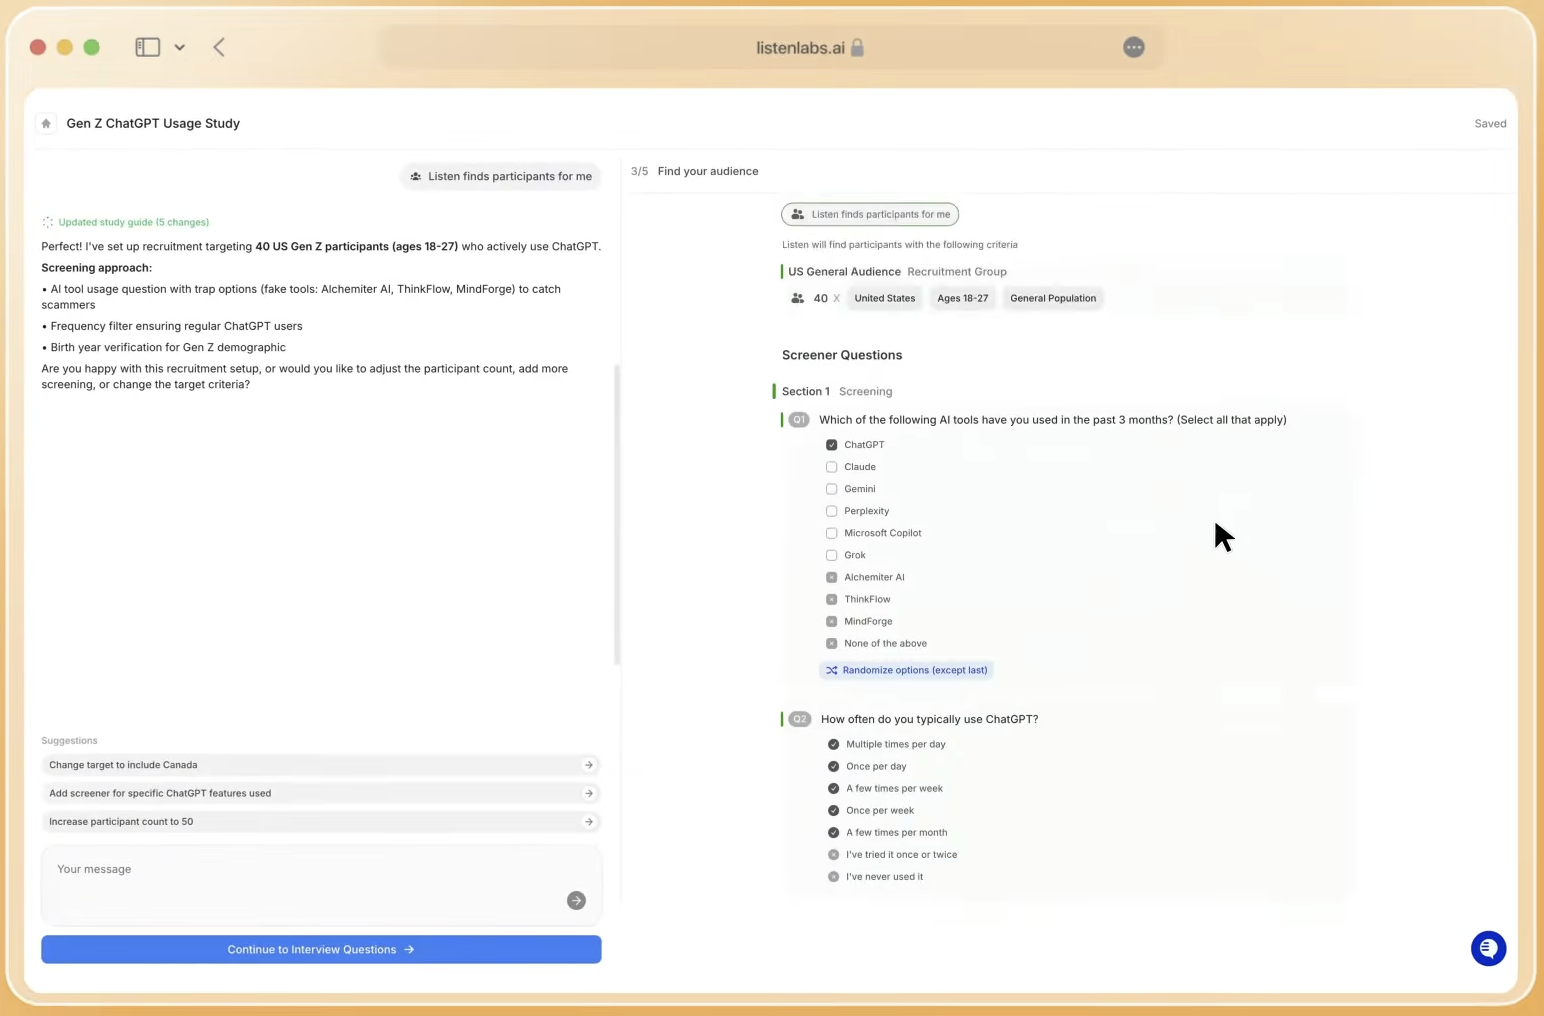
Listen Labs’ dedicated recruitment ops team sources audiences below 1% incidence rate, drawing on a network of 50M+ verified respondents across 45+ countries and 120+ languages. That infrastructure makes community-native recruitment operationally viable at tracking cadence, not just for one-off studies.
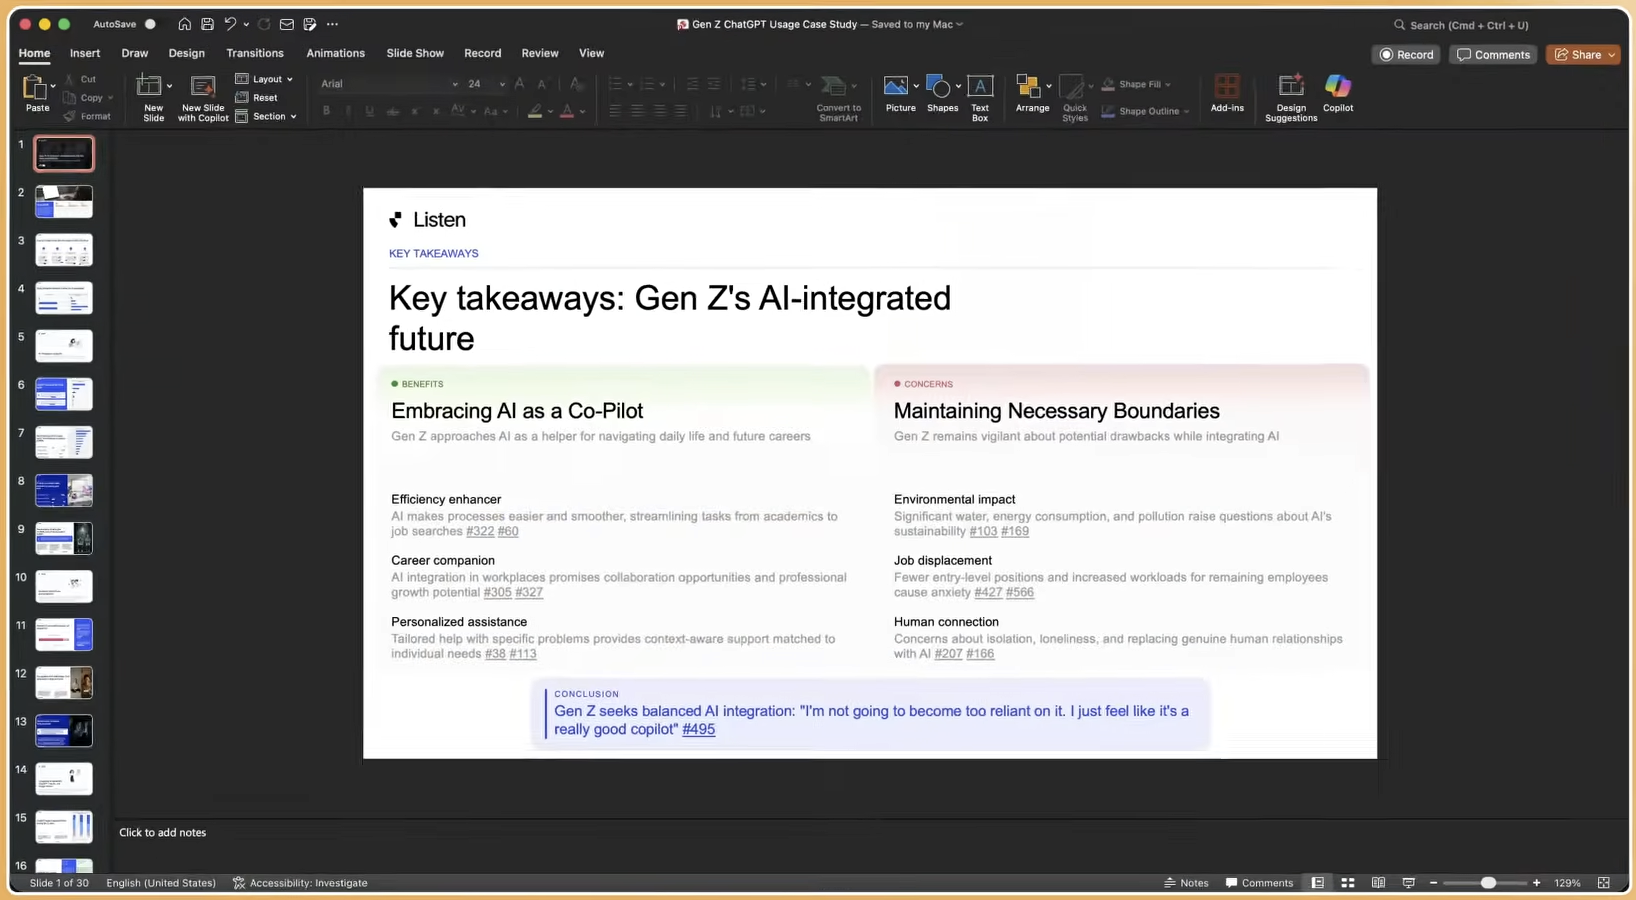
One well-known clothing brand, famous for its big logos, was quietly losing customers. Its old tracker caught the drop but could not explain it. Pulse found that the issue was style rather than price. A growing group of customers felt the big logos were too loud for their changing lifestyles. The tracker saw the number move, and Pulse found the reason in the same wave.
Book A Demo Of The Conversational Tracker
A Diagnostic You Can Run Today
Apply this test to your current tracker: ask whether the numbers would move if a specific segment disappeared from your tracker.
If the answer is no, the instrument cannot see the segment. The base is too small, the sourcing never reaches them, or the question set has no vocabulary for them. The segment exists in the market and remains absent from the data.
If the answer is yes, the segment is visible but the tracker still cannot tell you why it moved. You have a number without a diagnosis.
Either answer points to the same solution: a segment-valid tracker that addresses sample, sourcing, and question design together, rather than one layer at a time.
Frequently Asked Questions
How Many Respondents Do I Need Before A Subgroup Read Is Reliable?
N≥30 per cell is the practical floor for subgroup analysis. Below that threshold, subgroup means and percentages become essentially uninterpretable. As mentioned earlier, 100 or more respondents per subgroup is the recommended floor for meaningful comparisons. Sapio Research’s methodology guidance states that the minimum sample threshold applies to each subgroup individually, not to the total sample, so comparing three groups requires at least 100 respondents per group, not 100 spread across all three.
A total sample of 400 split across four segments leaves each segment with 100 respondents and a margin of error approaching ±10%. That level of precision rarely supports go-to-market decisions. Size each subgroup to the precision the decision requires, rather than to the total sample target.
Can Weighting Fix A Niche Segment That Is Missing From My Panel?
Weighting and post-stratification correct only for differences on variables actually measured and included in the weighting scheme. They cannot correct for unmeasured differences between responders and non-responders on the outcome itself. As noted earlier, weighting cannot correct for the structural under-representation of people who avoid online research.
A larger weighted sample drawn through the same flawed recruitment path produces a more precise estimate of the wrong number. The fix must happen at the recruitment stage, not at the analysis stage.
Does Adding Open-Ended Questions Break My Trend Line?
Open-ended questions do not break the trend line when core questions stay constant. As mentioned, wave-to-wave comparability is the tracker’s core value, so the trend line is protected by keeping the locked core questions identical. Adding a conversational open-ended layer alongside those questions does not alter the closed-ended metrics; it explains them.
A subtly changed core question between waves looks like a market shift when it is actually just a different question. That change is the real threat to trend integrity. The conversational layer sits alongside the locked core, so wave-to-wave comparability is preserved while every metric movement arrives with its explanation.
What Is The Difference Between A Demographic Cut And A Community Segment?
Demographics answer who someone is on paper, such as age, gender, income, and location. Community-based segmentation captures what people care about and how they actually cluster, based on observed behavior, shared interests, social graph connections, and cultural signals.
Demographic overlap reveals very little about what will motivate someone toward a brand. Two people with identical demographic profiles can hold entirely different values, trusted sources, and purchasing motivations. A demographic cut describes a statistical category. A community segment reflects a genuine cultural affiliation that persists across campaigns and seasons. For niche audiences in particular, the community segment is the unit that matters, and demographic cuts structurally cannot reach it.
Conclusion
Your tracker struggles because of three layers of design: sample, sourcing, and question design. Most teams only address the first. Oversampling addresses the arithmetic. Community-native recruitment addresses the sourcing gap that weighting cannot fix. Open-ended conversational tracking addresses the question design constraint that keeps niche vocabulary out of the data. Fixing one layer while leaving the others intact keeps the segment invisible.
Listen Pulse addresses all three layers while keeping the KPIs you already report, preserving the trend line, and capturing the “why” in the same wave. It deploys alongside an existing tracker or as the primary tracking system, integrates with Qualtrics and Decipher, and draws on Listen Labs’ 50M+ verified respondents and dedicated recruitment ops team to source audiences that general panels cannot reach.
Run A Segment-Valid Tracker With Listen Pulse