Written by: Anish Rao, Head of Growth, Listen Labs
Key Takeaways
- AI-powered continuous brand tracking pairs always-on conversational signal with representative survey waves so metric changes and their drivers arrive together.
- The two-layer model runs a high-volume conversational layer (10–100x survey volume) to surface emerging themes while the structured survey layer protects statistically reliable trend lines.
- AI codes open-ends, detects themes, and attaches a driver to every KPI movement, which removes the weeks-long lag of separate qualitative studies.
- Baseline-relative anomaly thresholds, composite alerts, and shadow-mode calibration keep alert volume manageable and prevent stakeholder fatigue.
- Listen Labs delivers Listen Pulse, a conversational tracker built to keep core questions constant, surface themes in real time, and close the loop from signal to action.
See how Listen Pulse keeps your brand tracker always on
The Gap Between “Make It Continuous” And Knowing How
Most brand and insights teams have been told to make their brand tracker continuous. Many guides explain why AI matters and stop before explaining how AI improves continuous brand tracking in practice, including data sources, cadence decisions, open-end coding, and how to keep the trend line trustworthy.
The stakes are concrete. A classic quarterly brand tracker delivers a panel-weighted snapshot with 8–16 weeks of total clock from field start to readout. By the time a KPI decline lands in a deck, the underlying shift has often been building for months. Continuous data enables causal reading that episodic research cannot support, because always-on measurement paired with a change log allows before-and-after comparison. A tracker that only reports that awareness or consideration moved leaves teams reacting to a lagging indicator with no diagnostic attached.
This article serves as a practitioner’s operating manual. It names real capabilities, real methodologies, real limitations, and a six-step diagnostic workflow teams can run.
Explore Listen Pulse for continuous brand tracking
Prerequisites And Context For Continuous Tracking
This manual assumes familiarity with brand-health metrics (awareness, consideration, purchase intent, NPS), survey wave structures, and basic qualitative research concepts. Before going further, the following terms need precise definitions.
- Continuous Brand Tracking: Collecting brand-health signal at a steady cadence rather than in discrete, time-bounded waves.
- Wave-Based Tracking: Fielding a survey to a defined sample at fixed intervals, most commonly quarterly, and comparing each snapshot against the last.
- Always-On Signal: Any data stream collected without a defined start and stop date, including conversational interviews, social listening, and search data.
- Representative Sample: A sample in which every member of the target population has a known, non-zero probability of selection, which enables formal statistical inference about that population.
- Open-End Coding: Assigning structured categories or themes to free-text responses.
- Theme Detection: AI identification of recurring patterns across large volumes of unstructured text.
- Anomaly Detection: Automated flagging of metric movements that exceed a predefined threshold relative to a baseline.
- Alert Fatigue: A condition in which monitoring systems fire so frequently that teams begin ignoring alerts, including genuine ones.
- Model Drift: Degradation in an AI model’s accuracy as the language, culture, or data distribution it was trained on shifts over time.
- Say-Do Gap: The divergence between what a participant states they prefer and what they actually do when observed.
Enterprises are shifting from one-off research projects to continuous customer intelligence programs, and AI has reached a maturity where it can conduct natural, adaptive conversations that approximate human-quality interviews, which is what makes qual-at-scale possible.
One credibility problem needs clear language upfront: social listening and conversational signal are not representative research. Social listening cannot produce statistically reliable estimates about the proportion of a population that holds a view; it can show that a concern exists and is gaining volume, but cannot determine whether 10% or 60% of an actual customer base shares that concern. Any honest treatment of AI brand tracking has to say so.
See how Listen Pulse pairs listening with representative surveys
How AI-Powered Continuous Brand Tracking Works
The six-step diagnostic workflow below covers the full operating cycle from data collection through closed-loop measurement.
- Collect Continuously, with always-on conversational signal plus representative survey waves running on their own cadence.
- Detect Change, with anomaly detection that flags movement beyond a predefined threshold rather than every fluctuation.
- Explain Drivers, as AI codes open-ends, detects themes, and attaches a driver to the movement.
- Alert, using tiered alerts that route to the right owner without crying wolf.
- Investigate, where the insights team drills into the theme, the verbatim, and the clip behind the number.
- Measure Response, tracking whether the action taken moved the metric and closing the loop.
Step 1: Define The KPIs The Tracker Must Protect
The workflow starts with the metric set, because every later decision, including cadence, thresholds, and alert routing, is defined relative to the KPIs the tracker is built to protect. Lock the funnel-aligned metric set before any data collection begins. The standard set includes unaided awareness, aided awareness, consideration, preference, usage or trial, brand associations, and NPS, and every metric added is a question that must be repeated forever.
The central decision at this stage is keeping core questions constant versus adding timely questions. Core questions stay fixed to protect the trend line, and timely questions cover new campaigns and competitors without breaking historical comparability. Moving a question between waves changes the context in which respondents answer it and can shift results on its own. A wording edit alone can move a brand relevance score by more than six points, which shows how sensitive the trend line can be.
Required inputs at this stage include existing tracker questions, KPI definitions, and historical trend data. Stakeholders include the insights team, brand and marketing, and analytics.
Step 2: Layer Always-On Conversational Signal On Top Of Representative Survey Waves
The organizing framework for AI-powered continuous brand tracking is a two-layer model. An always-on conversational layer catches emerging themes at high volume. Representative survey waves govern awareness, consideration, and purchase intent, which are the metrics leadership already trusts and the only layer that can measure people who have not yet bought, searched, or posted.
Survey-based tracking on a representative sample is the only method that can measure people who have not yet bought, searched, or posted at the reach and depth tracking requires. The structured layer remains essential.
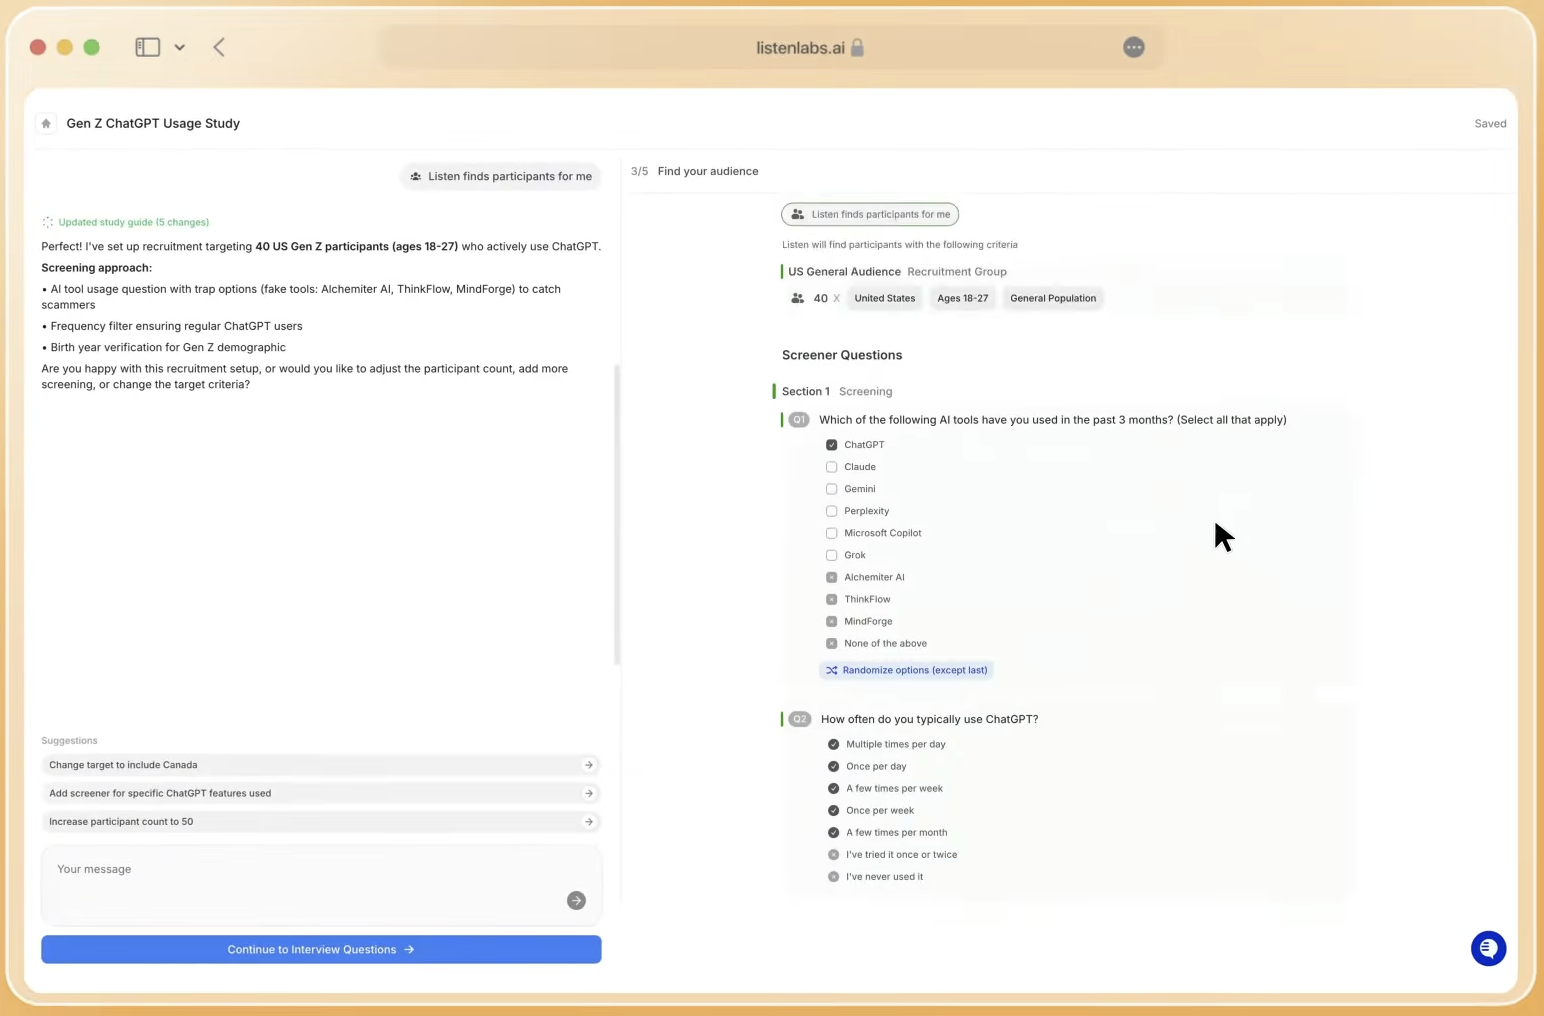
Run the conversational layer continuously at 10–100x the volume of the structured layer. That ratio is what leading brand teams in 2026 have converged on. They run a hybrid stack with a thin, weighted panel tracker quarterly, often at half the historical wave size, and a continuous AI conversation layer underneath at 10–100x the volume for qualitative “why” data.
Cadence determines how quickly the tracker can detect a real shift. A 4-week rolling average in a standard always-on design includes roughly 300–500 respondents, providing the same statistical reliability as a quarterly wave but updating every week. Daily versus weekly versus per-wave cadence depends on category velocity and budget. Fast-moving consumer categories benefit from tighter windows, while stable B2B categories with long buying cycles often remain on quarterly waves.
See the two-layer model in action
Step 3: Let AI Code The Open-Ends
AI processes unstructured data through NLP sentiment and emotion classification, theme and driver detection, and automated coding of open-ended responses. Every emotion is quantified per question and concept, with every label traceable to the exact timestamp, verbatim quote, and AI reasoning behind it, not just a sentiment score with no provenance.
Two methodologies deserve explicit mention: Ekman’s universal emotions framework for emotion classification, and Hierarchical Bayes for prioritization. These are checkable, established methods that a reviewer can verify against published frameworks. Listen Labs’ Emotional Intelligence feature is built on Ekman’s framework, tracking seven universal emotions across 50+ languages.
The core actions at this step are to sort open-ended answers into themes, quantify them, and chart each theme next to the KPIs already reported. Every insight links directly to the underlying response data, which keeps findings traceable before they go into a deck.
Coding at scale still leaves a question of who owns the output. The recommended division of labor is AI handles volume and the researcher handles claims, with every finding that will inform a decision traced back to underlying responses before it goes in a deck. AI handles the coding at scale, and the researcher validates which themes replicate and which are noise.
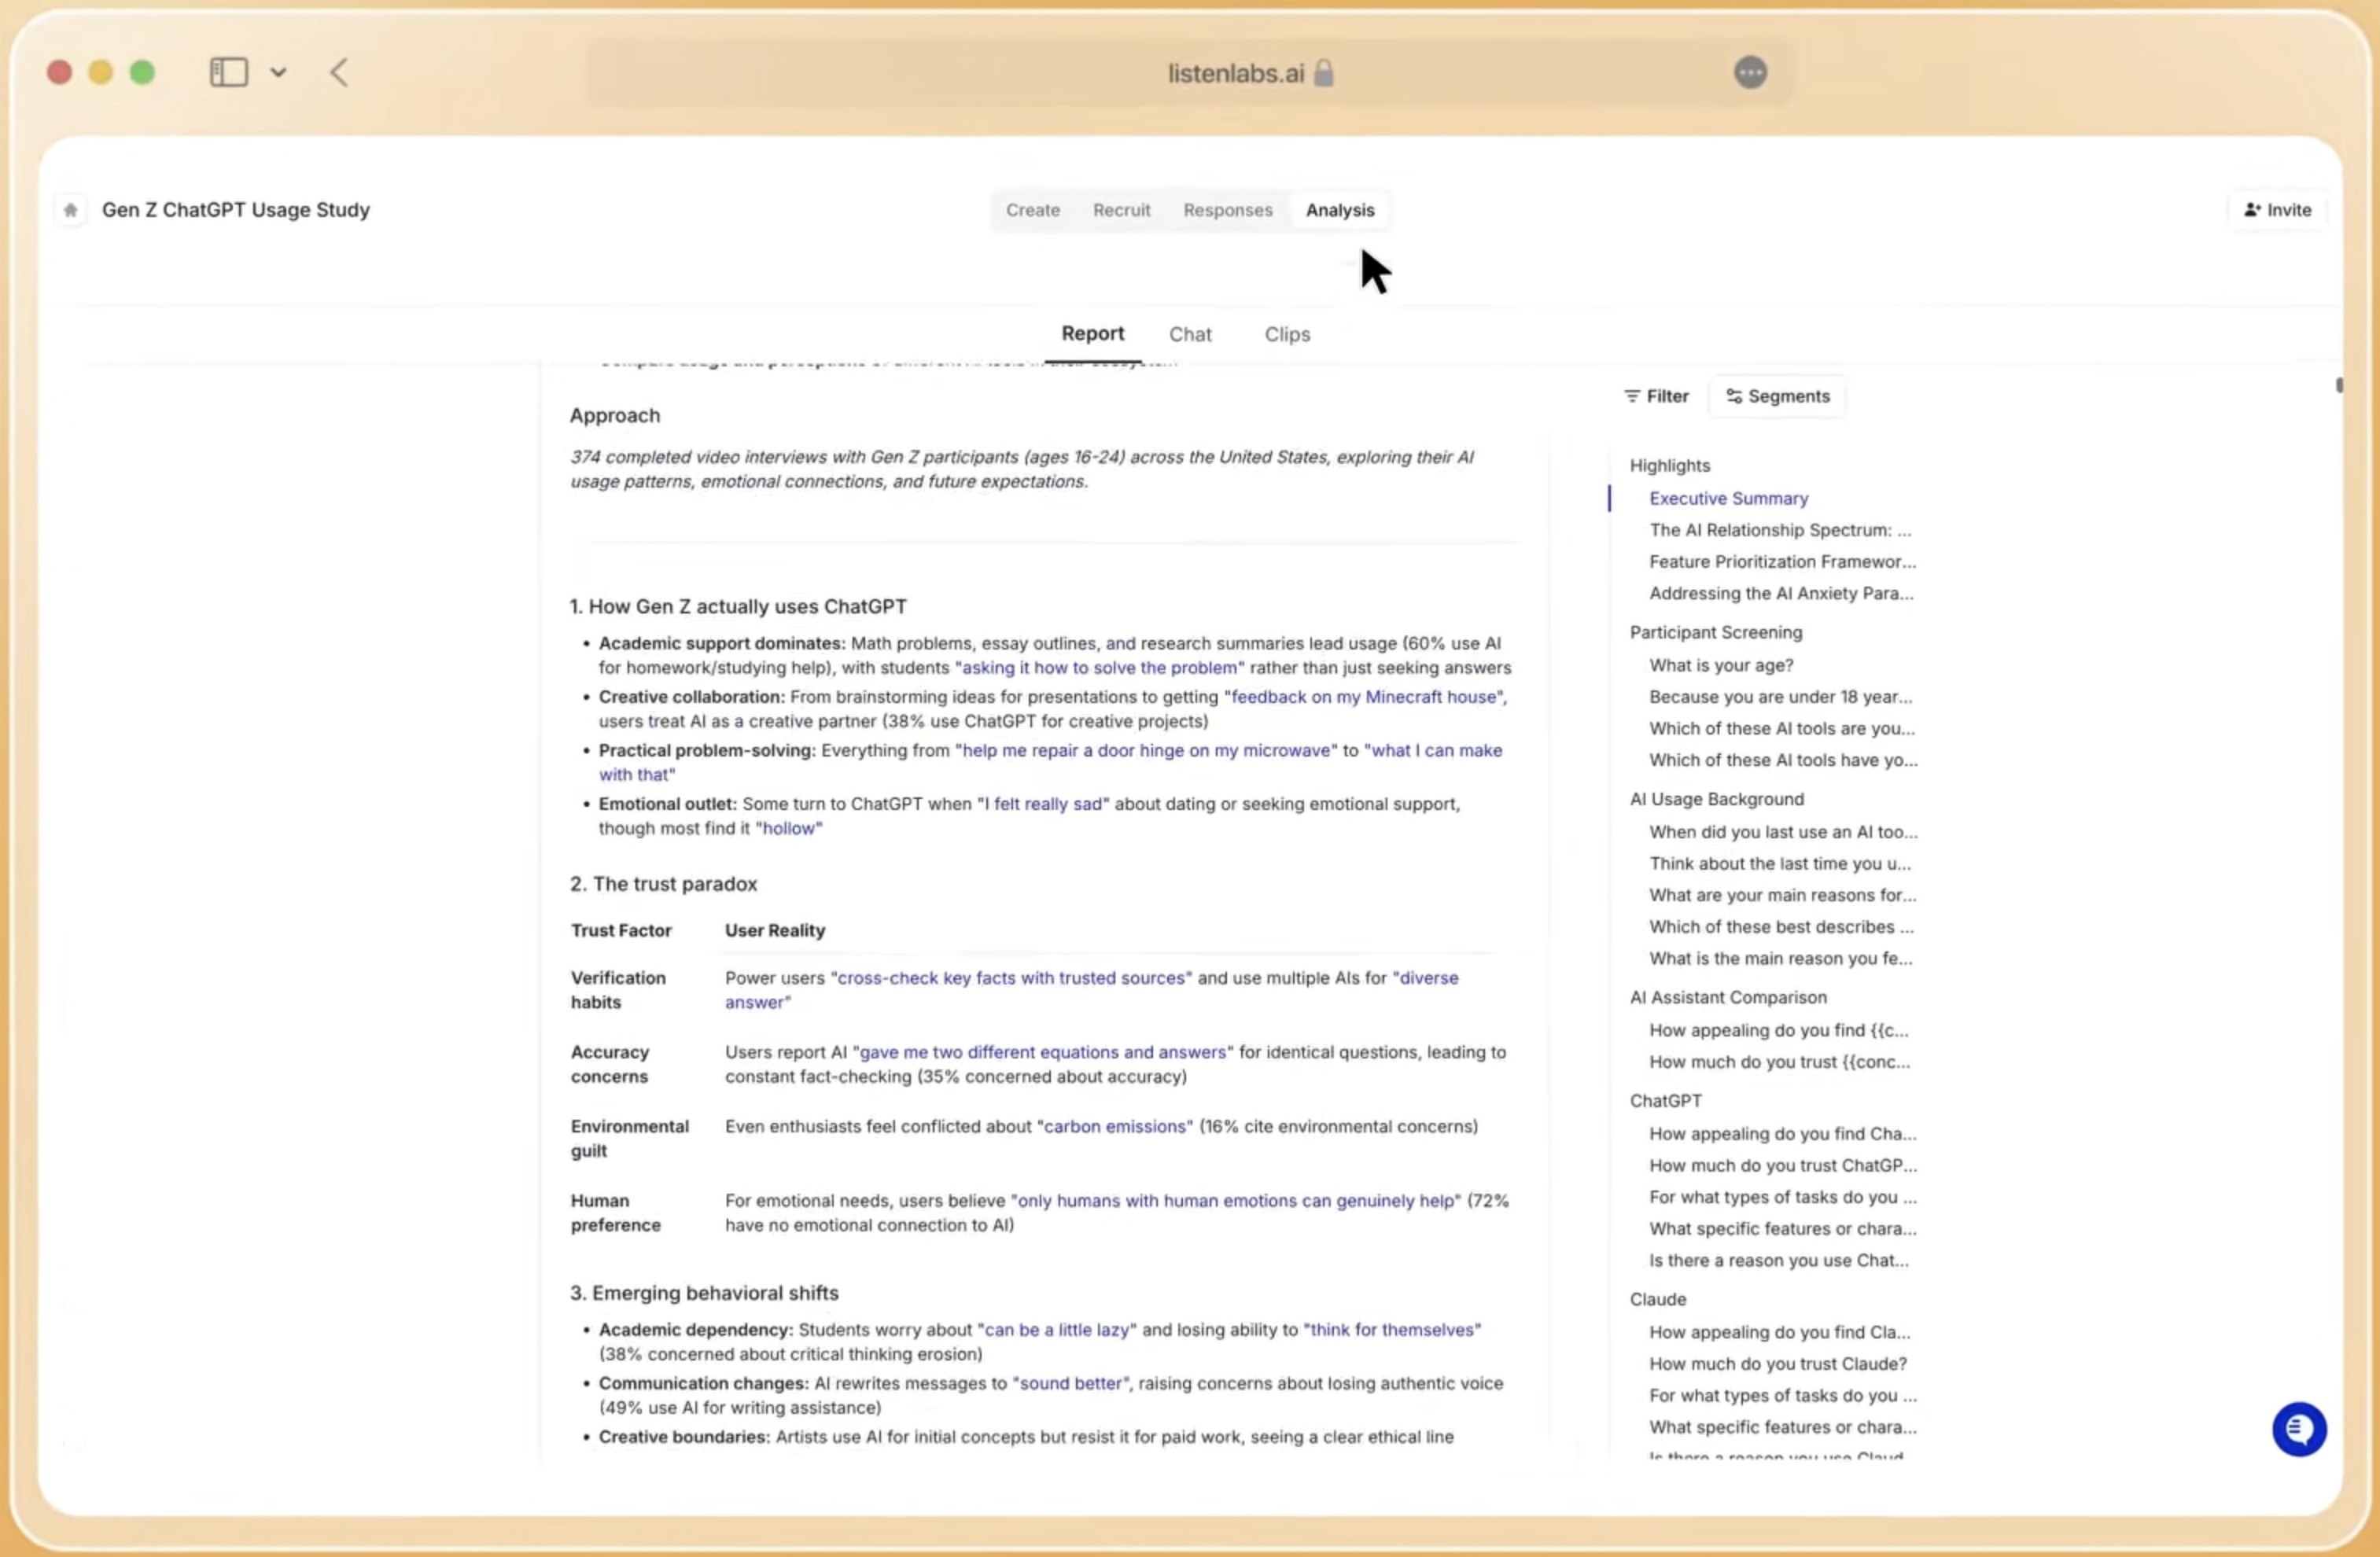
One credibility anchor comes from response depth. Open-ended responses captured via conversational AI run 12–20x longer per respondent than equivalent open-ended survey items; a survey-style open-ended brand question averages 8–15 words while the same prompt through an AI interviewer averages 180–400 words across 3–7 conversational turns. More signal per response supports more reliable theme detection.
Step 4: Set Anomaly Thresholds That Do Not Cry Wolf
Effective anomaly detection starts with a baseline. Establish a baseline before going live, then set alerts relative to that baseline rather than a fixed absolute cutoff. A baseline period of two to four weeks during which the monitoring system runs at full cadence without alerting enabled collects data on the natural variability of each metric before thresholds are set.
Three threshold-setting patterns do most of the work in reducing false positives, and they stack because each one catches a different class of noise.
- Rolling Means And Standard Deviations: Alert when a metric falls outside its historical 95th percentile range.
- Population Stability Index (PSI): PSI below 0.1 indicates no significant drift, 0.1–0.25 indicates moderate drift warranting investigation, and above 0.25 indicates significant drift requiring action.
- Composite Alerts: Requiring two or more signals to co-occur before firing is one of the most effective ways to cut false-positive rates. A typical composite rule pages only when PSI exceeds 0.15 on a key metric and prediction entropy rises at the same time.
Calibration keeps these patterns grounded in reality. Run the detector in shadow mode for two weeks before enabling paging alerts, logging every anomaly it would have fired and manually reviewing them; if fewer than 50% of logged anomalies are genuinely operationally significant, the threshold is too low.
See how Listen Pulse handles anomaly alerts
Step 5: Explain The Driver Behind Every Movement
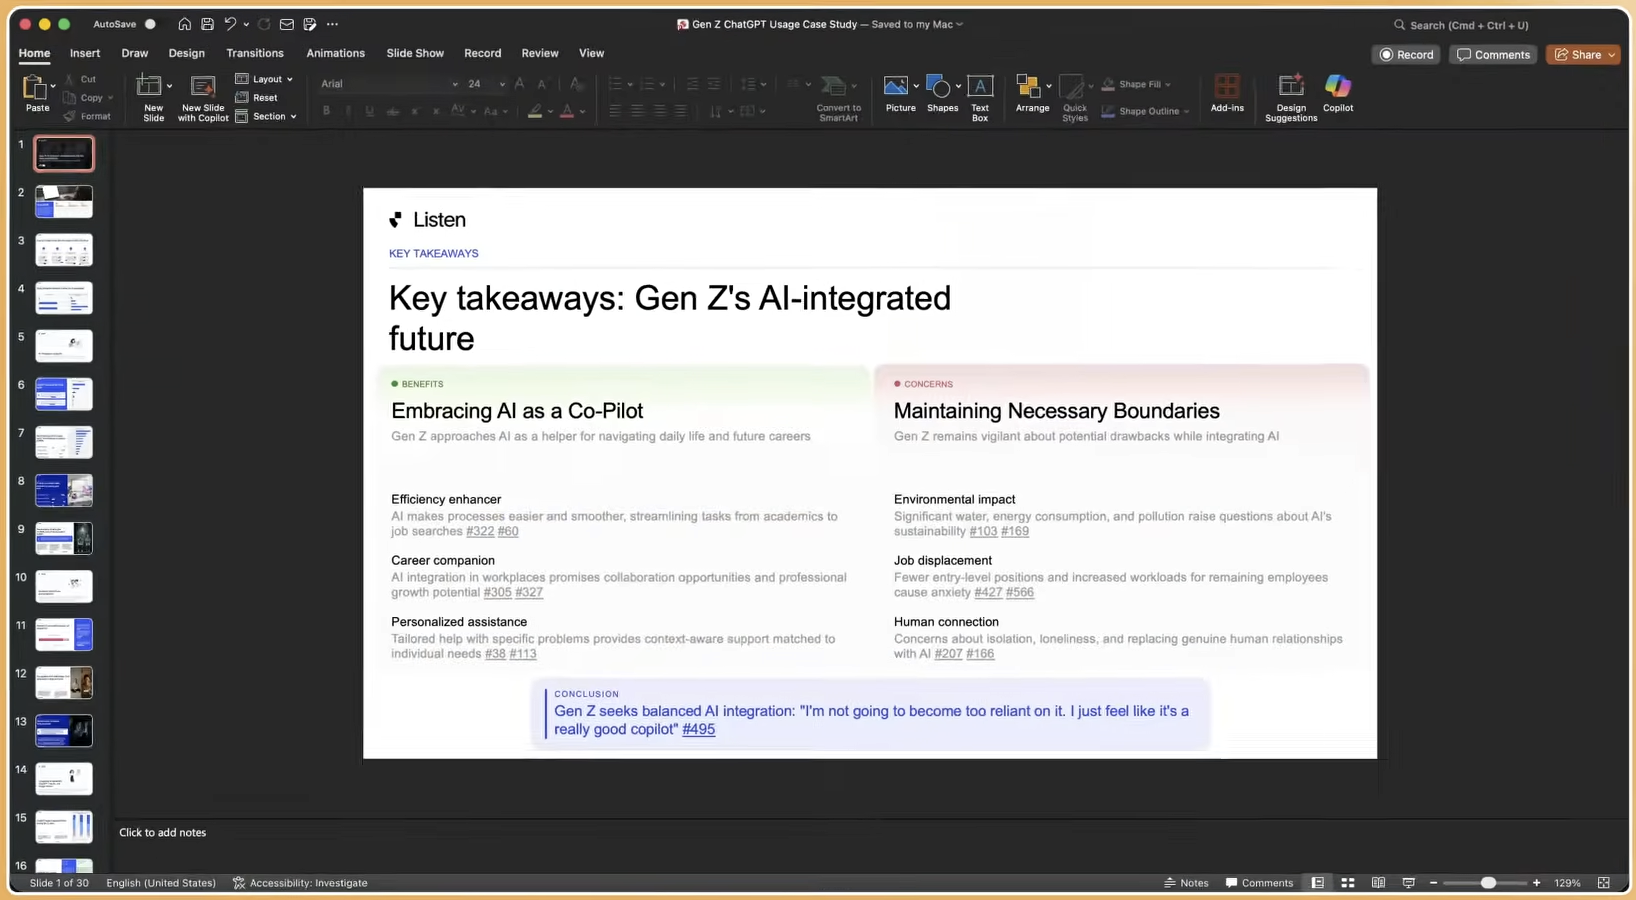
Attach a driver to every KPI movement so the metric change and the reason behind it arrive in the same wave. This step turns a continuous dashboard into a continuous diagnostic system.
A concrete example from Listen Pulse shows how this works. A clothing brand famous for its big logos was quietly losing customers. Its old tracker caught the drop but could not explain it. The always-on layer traced the decline to style rather than price. A growing group of customers felt the big logos were too loud for their changing lifestyles. That finding arrived with the metric movement instead of six weeks later after a separate qualitative study.
To answer the “why” behind tracker movements, brand teams have historically commissioned a separate qualitative study of 4–8 focus groups at $8,000–$15,000 per group, adding another $50,000–$120,000 and 6–10 weeks. The two-layer model removes that lag by building the diagnostic into the same instrument.
The human-in-the-loop principle applies here too, and the split is clean. AI can schedule and conduct the interview, analyze transcripts for themes, and generate quantitative insights from those interviews, but the researcher determines which driver explanation is credible enough to inform a decision.
See how Listen Pulse explains KPI movements
Step 6: Close The Loop By Measuring Response
Closed-loop tracking connects actions back to outcomes. Track whether the action taken moved the metric, and record what changed and when in a change log rather than just a dashboard. Investing in a change log rather than just a dashboard is what makes continuous data interpretable, since recording what changed and when is what enables before-and-after comparison.
Always-on measurement paired with a change log allows causal reading that episodic research cannot support. A campaign launches on March 1. The always-on layer shows awareness moving by March 15. The change log records the launch date. The connection is traceable without a separate brand lift study.
Stakeholders at this stage include the insights team, brand and marketing, and product. The program is working when KPI movements arrive with a driver attached and stakeholders use the tracker in decisions, regardless of how populated the dashboard looks.
See how Listen Pulse closes the loop
Common Challenges And Troubleshooting
Running the six-step workflow in practice surfaces a predictable set of failure modes. Each has early warning signs and realistic remedies.
Alert Fatigue From Over-Sensitive Anomaly Detection. The warning sign is alert volume that exceeds 15 per week during normal conditions. The cause is thresholds set too low or without a baseline calibration period. The remedy is to run shadow mode for two to four weeks, review the alert log monthly, and classify true versus false positives to recalibrate.
False Alarms That Erode Stakeholder Trust. The warning sign is stakeholders who stop acting on alerts or stop opening dashboards. The cause is missing composite alert requirements and single-signal triggers firing on noise. The remedy is to require two or more signals to co-occur before paging and to tier severity so only P1 alerts reach leadership.
Model Drift As Language And Culture Shift. The warning sign is themes that do not replicate in the next wave or coded categories that no longer match the language respondents actually use. The cause appears when an organization keeps running the same tracker on the same panel with the same instrument while the respondent population and data quality environment change, so the trend line becomes a measure of the method rather than the market. The remedy is to monitor PSI on input distributions, schedule periodic method reviews, and retrain or recalibrate models when PSI exceeds 0.25.
Social Or Conversational Data Mistaken For Representative Research. The warning sign is a team that reports awareness figures from conversational data without confidence intervals. The cause is a two-layer model that is not clearly documented internally. The remedy is to sequence listening and survey research rather than substituting one for the other, where listening surfaces themes and language people actually use and survey research then measures how widespread each theme is across a defined population.
The Say-Do Gap. The warning sign is stated preferences in the tracker that do not predict observed behavior in sales or behavioral data. The cause is self-report bias, where participants answer what they think is expected. The remedy is to pair stated preference data with observed behavioral signals where available and treat stated preference as directional rather than predictive.
Governance Gaps Around AI-Coded Themes. The warning sign is themes that appear in reports without a researcher having reviewed the underlying verbatims. The cause is the absence of a defined human-in-the-loop checkpoint. The remedy is to assign a named reviewer for each wave’s theme output before findings go into a stakeholder deck.
AI continuous brand tracking also has clear limits.
- It does not deliver statistically representative claims by default. Teams should keep a thin representative tracker running alongside the conversational layer.
- It remains subject to model drift as language and culture shift. Teams should monitor PSI and schedule periodic recalibration.
- It does not close the say-do gap on its own. Teams should pair stated preference with observed behavioral data where available.
See how Listen Pulse manages these risks
Measuring Success: How To Know The Program Is Working
Clear indicators show when the continuous tracking program is doing its job.
- Themes detected in the conversational layer replicate in the next representative survey wave.
- The share of KPI movements that arrive with a driver attached increases over time.
- Time from signal to explanation decreases, ideally from weeks down to days.
- Stakeholders reference the tracker in decisions rather than commissioning separate studies to explain movements.
- Alert volume stays within the 3–8 actionable alerts per week range during normal conditions.
Practical tracking mechanisms include a standing weekly review cadence for the brand team, monthly summaries for marketing leadership, quarterly deep dives with competitive benchmarking for executives, and periodic retrospectives on which alerts proved real. Alerts should trigger investigation rather than panic; most alerts will be noise, but the ones that are not will justify the entire program.
Core questions should stay constant wave over wave, and timely questions should cover new campaigns and competitors without breaking historical comparability. Switching methods mid-program breaks comparability and requires rebaselining, which becomes an avoidable cost with disciplined instrument design from the start.
Review your current tracker with Listen Pulse
Advanced Considerations: Where Continuous Tracking Goes Next
Teams with a functioning two-layer model can extend into several advanced directions. These include always-on research programs across multiple markets, global and multi-market tracking with localized screeners, integrating behavioral and on-screen data to narrow the say-do gap, advanced segmentation by purchase stage or category entry point, and emotion signal analysis layered onto quantitative KPIs.
The freshest dimension of continuous brand tracking is brand visibility inside AI search engines, including how ChatGPT, Gemini, and Perplexity describe a brand in their generated answers. One in four customers now cite AI-powered platforms as their primary discovery tool, ahead of brand websites and online reviews, and brands appearing in AI answers convert customers at 4.4x the rate of organic search. 49% of marketers now actively monitor LLM impact on brand visibility, up from 22% in 2025, more than doubling in twelve months.
Tracking AI search visibility operationally means running a fixed prompt set across ChatGPT, Gemini, Perplexity, and Google AI Overviews on a schedule, recording mentions, citations, and how each engine characterizes the brand, and tracking share of voice over time. AI Share of Voice is calculated as the number of responses that mention a brand divided by the total responses executed, so a SoV of 20% means the brand appears in 1 out of every 5 relevant responses from that model. Platforms addressing this dimension include Kantar’s AI Signals, Qualtrics brand tracking, and Adobe Brand Visibility Solutions.
For teams building or expanding a continuous tracking program, Listen Labs has conducted over 1 million AI-powered customer interviews for companies including Microsoft, Perplexity, and Sweetgreen. Listen Pulse is the conversational tracker purpose-built for this problem. It runs the same study with the same screeners wave after wave and keeps core questions constant to protect the trend line. Every wave adds open-ended conversation, which Pulse sorts into themes, quantifies, and charts next to the KPIs a team already reports.
Pulse analyzes tens of thousands of responses 24/7, surfaces trends forming now, deploys alongside an existing tracker or as the primary tracking system, and integrates with Qualtrics and Decipher so teams keep the KPIs they already report.
Every number in Listen Pulse traces back to a real moment with a real person, including their words, the quote, and the clip. Listen never trains its AI models on customer data and holds SOC 2 Type II, ISO 27001, ISO 27701, ISO 42001, and GDPR compliance. The platform covers more than 50M verified respondents across 45+ countries and 120+ languages, and delivers results in less than 24 hours. Listen Labs raised a $69M Series B led by Ribbit Capital in January 2026.
For teams piloting, a phased approach works best. Run the always-on layer alongside the existing tracker for a wave or two, compare themes against the structured results, and phase in new question types before retiring anything. Moving one tracker to continuous before moving all of them, proving a team can act on always-on data with a single instrument before restructuring the whole program, is the recommended sequencing.
Plan a phased rollout with Listen Pulse
Conclusion
The lagging-indicator problem described at the start is what the two-layer model is built to solve. By the time a KPI decline lands in a deck under a traditional design, the underlying shift has often been building for months, and explaining it usually requires a separate qualitative study that adds weeks and cost.
Listen Pulse acts as the always-on diagnostic layer that sits on top of the representative brand-health tracker a team already runs. It keeps core questions constant to protect the trend line, adds open-ended conversation to every wave, sorts answers into themes, quantifies them, and charts each theme next to the KPIs teams already report. Every metric traces back to a real moment with a real person, including their words, the quote, and the clip, so the metric change and the reason behind it arrive in the same wave.
See Listen Pulse in a live demo