Written by: Anish Rao, Head of Growth, Listen Labs
Key Takeaways
Five principles determine whether a brand-tracking movement is real and worth acting on. These points connect the statistics, the limits of your sample, and the story behind the numbers.
- Statistical significance testing separates real brand metric movements from sampling noise by using sample size, effect size, and variance.
- The two-proportion z-test with pooled standard error is the correct method for comparing brand tracking waves, while confidence intervals use unpooled standard errors.
- Design effects from weighting reduce effective sample size, so practitioners need to report effective rather than nominal sample sizes when making significance claims.
- Multiple testing across many KPIs and segments inflates false positive risk, so corrections like Holm’s procedure or Benjamini-Hochberg keep results credible.
- Listen Labs combines statistical rigor with qualitative explanation so teams can both prove that movements are real and understand why they happened.
How To Test Significance Between Two Brand Tracking Waves
Consider a tracker fielded to n=1,000 per wave, with unaided awareness at 42% in Wave 1 and 46% in Wave 2. That four-point change looks meaningful on a chart, yet it still needs a proper test.
The correct procedure is the two-proportion z-test. Under the null hypothesis that both waves share the same true proportion, the pooled estimate is p̂ = (420 + 460) / 2,000 = 0.44. The pooled standard error is √[0.44 × 0.56 × (1/1,000 + 1/1,000)] ≈ 0.0222. The test statistic is z = 0.04 / 0.0222 ≈ 1.80, giving a two-sided p-value of approximately 0.072.
At the conventional 95% confidence level, this movement does not clear the bar. The 95% confidence interval for the change uses the unpooled standard error, √[0.42 × 0.58/1,000 + 0.46 × 0.54/1,000] ≈ 0.0221. That gives a margin of error of approximately 0.0433 and a 95% CI of roughly −0.3 to +8.3 percentage points. The interval includes zero.
A distinction that trips practitioners up: the test pools because it assumes no difference under the null, while the confidence interval does not pool because it estimates the effect directly. Using the wrong standard error in either place is a common and consequential error.
The reporting sentence a practitioner can paste into a deck: “Unaided awareness moved from 42% to 46%, a difference of 4.0 percentage points (95% CI: −0.3 to +8.3; z = 1.80, p = 0.072). The change is not statistically significant at the 95% level.”
Confidence Level And Sample Size: Think In Minimum Detectable Change
The 95% confidence convention is widely cited, and common brand-tracking wave sizes in the evidence range from roughly 200–500 respondents per wave. The number a practitioner actually needs is the minimum detectable change (MDC), which is the smallest shift a two-wave comparison can reliably surface.
At 95% confidence and 80% power, the smallest change a two-wave comparison can reliably detect requires approximately 2.8 standard errors. That is roughly twice the margin of error of a single wave. In practical terms:
- At n=1,000 per wave, the MDC for a metric near 50% is about 6.3 percentage points.
- At n=400 per wave, the MDC rises to about 9.9 points.
- At n=2,000 per wave, the MDC falls to about 4.4 points.
A 4-point move at n=1,000 sits below the detection threshold. That matches the worked example. The implication for segments is severe. Splitting 1,000 respondents across five segments gives each segment an MDC of around 14 points, so most segment-level “movements” are statistically unreadable.
Why Weighting And Design Effects Change Your Significance Test
Even a correctly computed z-test can overstate precision, because every weighted tracker operates with a design effect, the ratio of the variance under the actual sample design to the variance under a simple random sample of the same size. Effective sample size is the nominal n divided by the design effect.
A real-world benchmark helps. The UK Department for Energy Security and Net Zero Public Attitudes Tracker Spring 2026 reported a design effect of approximately 1.68 and an effective sample size of about 2,022 from an achieved sample of 3,389. That is roughly 60% efficiency. Design effects of 1.5 to 1.7 are routine in weighted trackers, and even straightforward quota-based online surveys commonly land at 1.2 to 1.5.
Re-running the worked example with a design effect of 1.5 changes the conclusion materially. The standard error scales by √1.5 ≈ 1.22, so the standard error of the difference becomes roughly 0.0271. The z-statistic falls to about 1.48, the p-value rises to roughly 0.14, and the confidence interval widens to approximately −1.3 to +9.3 points. A movement that was already not significant becomes clearly not significant.
The operational consequence is simple. A tracker with n=1,000 per wave and a design effect of 1.5 behaves statistically like a simple random sample of about 667. Report the effective sample size, not the nominal one, whenever making a precision claim. Respondents are often grouped by market, panel, or recruitment batch. When that happens, intraclass correlation compounds the design effect. Analyzing clustered data as if it were independent then understates standard errors and inflates false positives.
The Multiple Testing Problem In Brand Trackers
A tracker testing 20 independent KPIs at α = 0.05 has a 64% chance of at least one false positive per wave even if nothing moved. At 50 tests the chance rises to 92%. A standard quarterly tracker with five banner variables and nine headline metrics produces 45 segment-by-metric comparisons before any wave-over-wave analysis.
Two corrections address this directly:
- Holm’s step-down procedure controls the family-wise error rate, the probability of even one false claim, and is the right choice for a small confirmatory family where a wrong claim is expensive. Holm is uniformly more powerful than Bonferroni while controlling exactly the same error rate.
- Benjamini-Hochberg controls the false discovery rate, the expected proportion of declared findings that are false, and is the right choice for exploratory screening across many secondary metrics. It was introduced by Benjamini and Hochberg in their 1995 Journal of the Royal Statistical Society paper and offers substantially more power than FWER-controlling procedures when many tests are run.
The plain rule follows from these two corrections. Pre-specify one primary metric per wave and test it at α = 0.05 unadjusted, because a single confirmatory claim does not need correction. Apply Benjamini-Hochberg at q = 0.10 to everything else, since exploratory metrics need false-discovery control rather than family-wise control. Treat every significant segment cut as a hypothesis rather than a finding, because a segment result that survives correction still needs an explanation before it can drive a decision.
Statistical Significance Vs. Practical Significance In Brand Metrics
With a large enough sample, a 0.2-point awareness move can clear p < 0.05 and still be worth nothing. The p-value depends on both effect size and sample size, so it is not a measure of importance. A p-value of 0.0001 from 100,000 observations can describe a smaller effect than a p-value of 0.04 from 50 observations.
Effect size should drive the decision. Set a minimum effect of interest before the wave fields, defined as the smallest movement that would change a budget, a message, or a plan. Treat anything below that threshold as a non-result regardless of its p-value. Pairing every significance claim with an effect-size claim and a cost-of-being-wrong claim before any budget moves is the standard a complete analysis requires.
The asymmetry that matters for trackers is simple. Brand metrics move slowly, so a genuine three-point annual gain is a real result. If each wave carries five to seven points of sampling noise, that gain only surfaces clearly after pooling several waves.
A Decision Framework Before You Call A Movement Significant
Use this checklist before the Monday leadership meeting so every claimed movement rests on a clear chain of reasoning.
- Confirm the question was pre-specified and the metric was not chosen after seeing the data, because everything downstream depends on this.
- Compute the two-proportion z-test with the pooled standard error, then compute the confidence interval with the unpooled standard error, since the two use different standard errors for a reason.
- Check whether that interval excludes zero at your chosen confidence level, because this is the actual significance decision.
- Divide nominal n by the design effect and re-check the test on the effective sample size, which reflects the real precision of the tracker.
- Count how many comparisons you are making, then apply Holm for a confirmatory family or Benjamini-Hochberg for exploratory metrics so multiple testing stays under control.
- Compare the effect against your pre-set minimum effect of interest, which sets a higher bar than zero and keeps trivial movements out of the deck.
- Check whether the movement holds across two or three consecutive waves before treating it as a trend, because single-wave spikes often fade.
- If it survives all eight steps, ask why it moved and get an answer from the people behind the number.
Run a statistically sound tracker
The Solution: Listen Pulse, The Conversational Tracker
Clearing the statistical bar answers whether a movement is real. It still leaves the reason for that movement open. That gap is where most trackers stop, and where Listen Pulse begins.
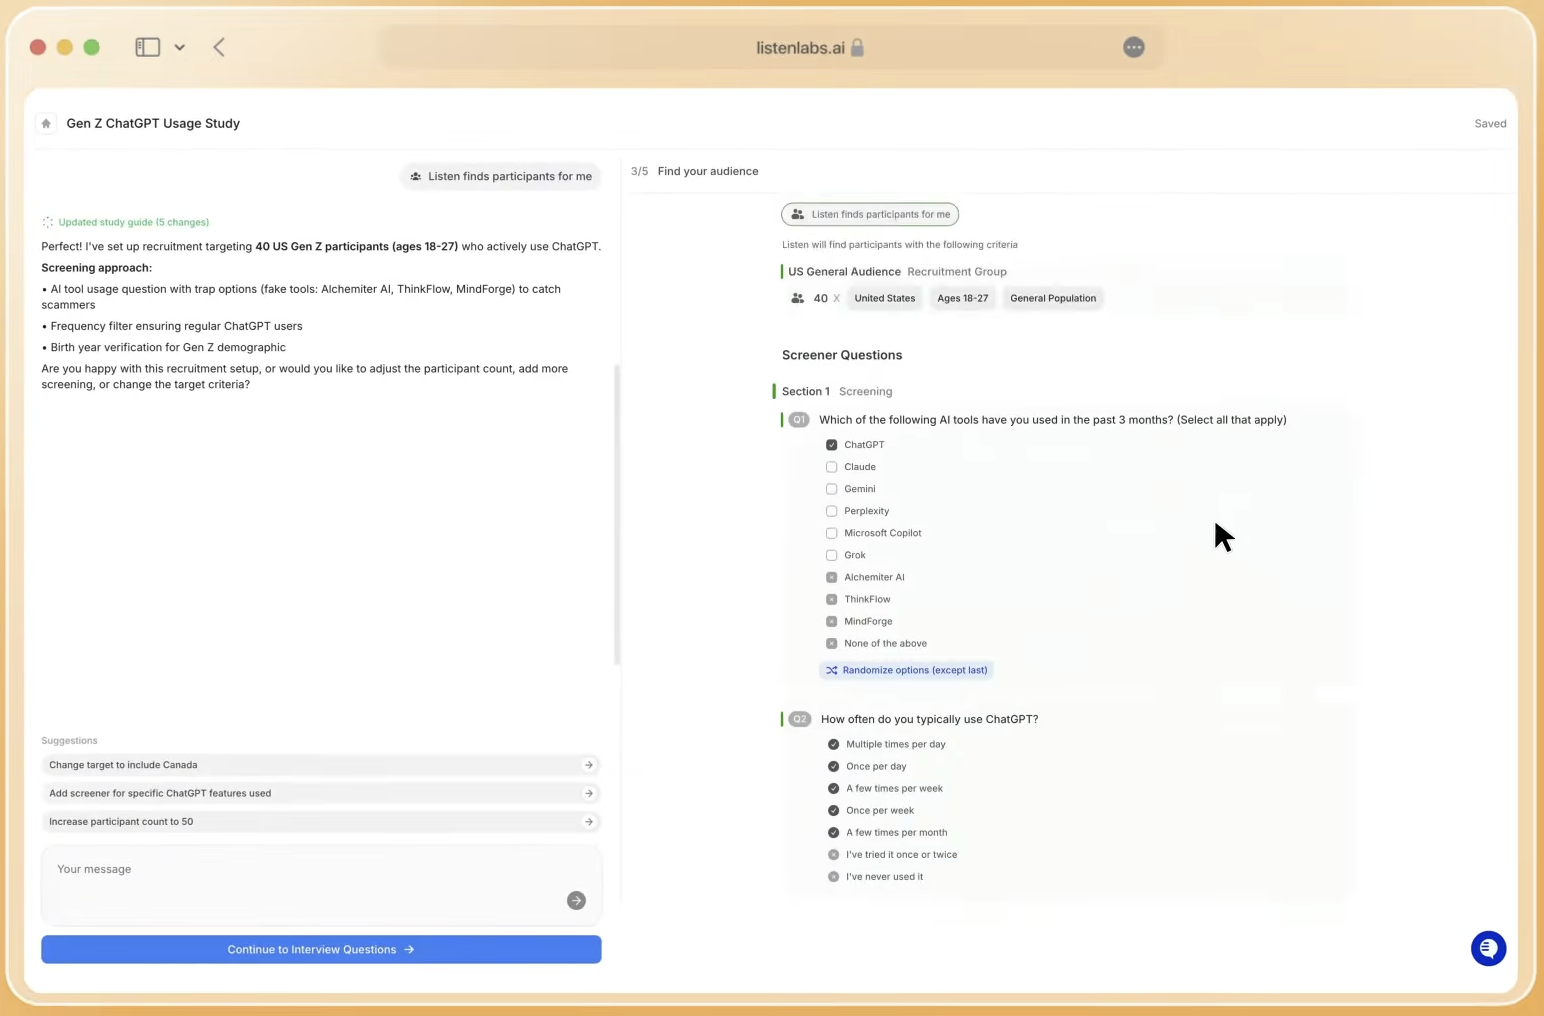
Listen Pulse is Listen Labs’ conversational brand tracker, built for teams that need both statistically sound tracking and the qualitative explanation attached to every metric movement, delivered in the same wave. Its core capabilities:
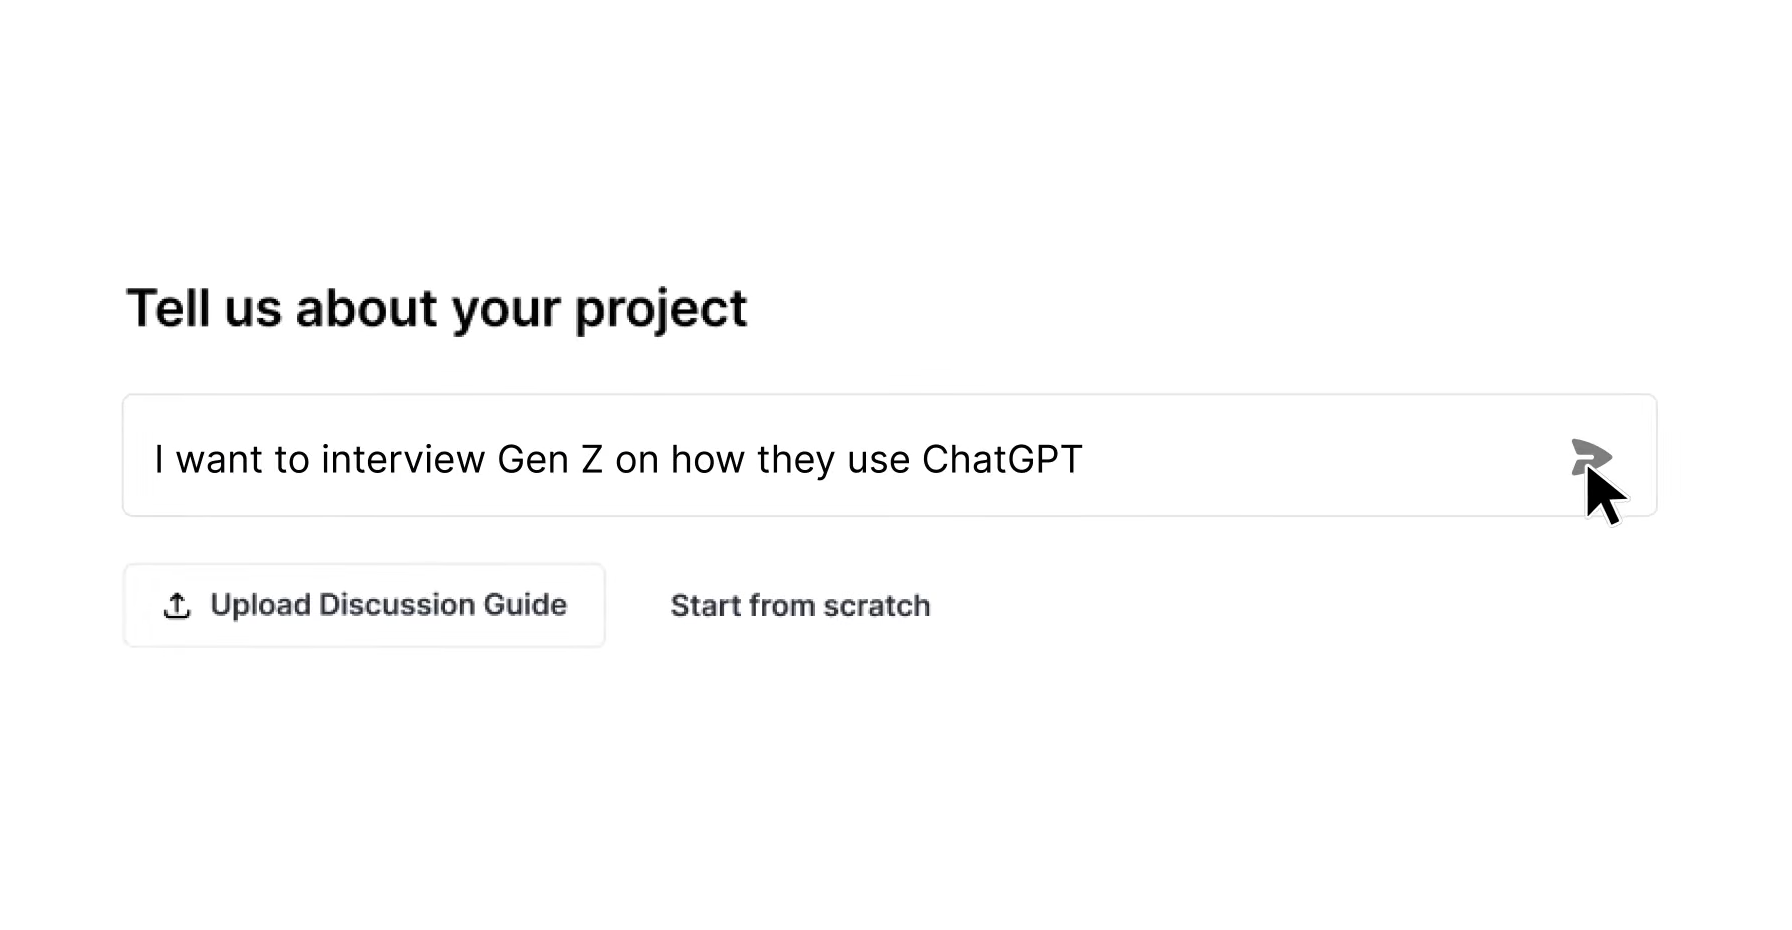
- Runs the same study with the same screeners wave after wave, keeping core questions constant to protect the trend line.
- Adds open-ended conversation to every wave, so every metric movement arrives with its explanation.
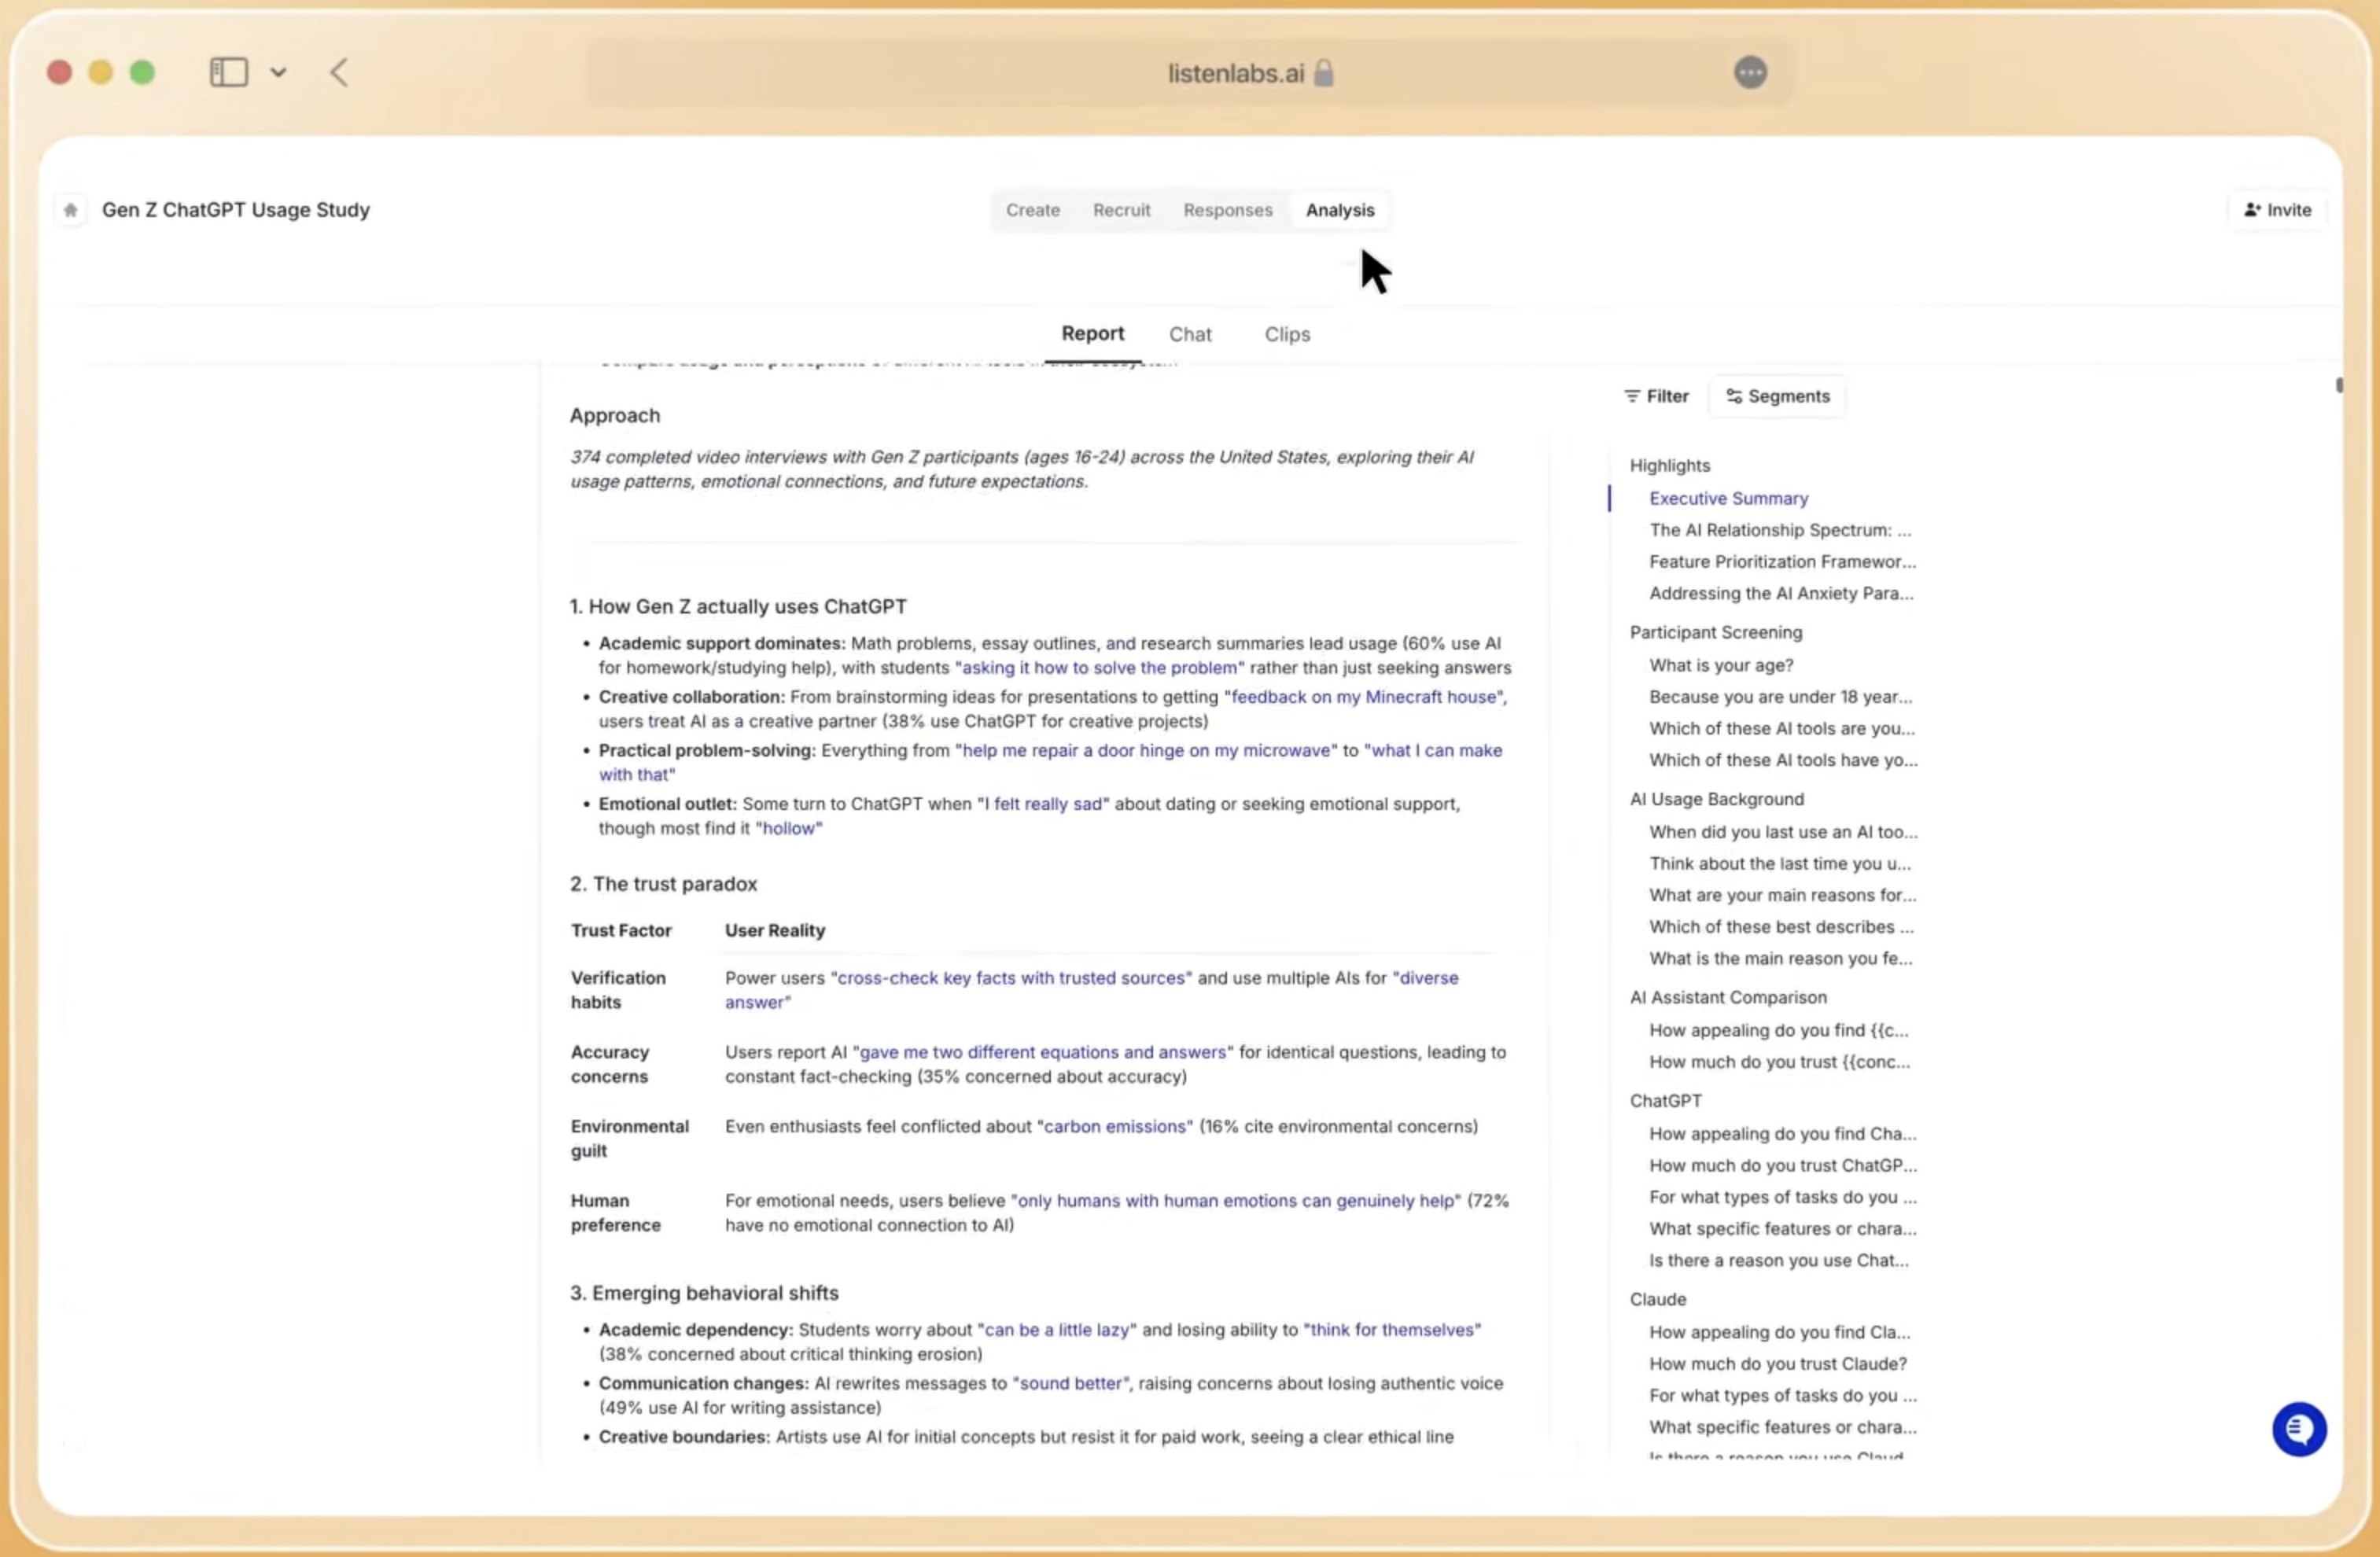
- Sorts and quantifies open-ended answers into themes and charts each theme next to the KPIs teams already report.
- Traces every number back to the interview, verbatim quote, and audio or video clip behind it.
- Analyzes tens of thousands of responses around the clock and surfaces trends before they hit KPIs.
- Integrates with Qualtrics and Decipher, and deploys alongside an existing tracker or as the primary tracking system.
A well-known clothing brand famous for its big logos was quietly losing customers. Its old tracker caught the drop but could not explain it. Pulse found the cause was style, not price. A growing group of customers felt the big logos were too loud for their changing lifestyles. The metric and the reason arrived together, in the same wave.
Frequently Asked Questions
Is A 4-Point Change In Brand Awareness Statistically Significant At n=1,000 Per Wave?
No, not at 95% confidence. The worked example above shows this move lands at p ≈ 0.072, and applying a routine design effect of 1.5 pushes it further from significance. For the full calculation, see “How To Test Significance Between Two Brand Tracking Waves.”
What Sample Size Do You Need For Brand Tracking Significance?
The sample-size section above gives the full MDC table. In short, 200–500 respondents per wave is a floor for directional reads rather than a threshold for defensible significance claims, and segment-level reads need their own base.
Why Does Weighting Make My Significance Test Less Sensitive?
Weighting inflates variance and shrinks the effective sample size. The design-effect section above shows how a design effect of 1.5 can make a 1,000-respondent tracker behave like a 667-respondent simple random sample. Scale standard errors by the square root of the design effect and report effective n whenever you talk about precision.
Should You Correct For Multiple Testing In A Brand Tracker?
Yes, whenever you make more than one claim from a wave. The multiple-testing section above explains how uncorrected testing inflates false positives and outlines when to use Holm and when to use Benjamini-Hochberg.
Conclusion: Prove The Movement, Then Explain It
The two-proportion z-test is the right starting point for brand tracking statistical significance. Weighting, design effects, and multiple testing usually mean the movement is smaller than it looks. Even a number that clears the statistical bar leaves the why unanswered.
Listen Pulse is built for teams that need both. It delivers statistically sound tracking wave over wave, with the qualitative explanation attached to every metric movement in the same wave. The metric and the reason arrive together, before the Monday meeting, traceable to the exact interview and the exact words behind the number.