Written by: Anish Rao, Head of Growth, Listen Labs
Key Takeaways On Predictive Analytics In Consumer Research
- Predictive analytics in consumer research forecasts future buyer behavior using historical data and machine learning. Descriptive analytics focuses on explaining past events.
- Five model families cover most consumer research needs. Logistic regression handles binary outcomes like churn, decision trees segment customers by behavioral rules, random forests and gradient boosting handle complex interacting variables, and neural networks suit high-dimensional data such as clickstreams.
- High-value applications include purchase probability, churn prediction, customer lifetime value, campaign response, and next-best-action recommendations that connect directly to research decisions.
- Predictive models always carry uncertainty. Overfitting, data leakage, biased training data, concept drift, limited interpretability, and privacy constraints all reduce accuracy on new data.
- Listen Labs connects predictive targeting with qualitative explanation through AI-moderated interviews and Emotional Intelligence analysis that generate structured data for modeling workflows.
How Predictive Analytics Works In Consumer Research
A predictive analytics workflow in consumer research follows six sequential stages, and each stage supports a specific research decision.
- Data Collection. Gather survey responses, interview transcripts, behavioral signals, and purchase history. A churn study might combine CRM records, session-frequency logs, and open-ended interview data from at-risk accounts.
- Data Preparation. Clean, normalize, and engineer features, then handle missingness and outliers. All data-dependent cleaning operations such as imputation values, outlier thresholds, and normalization parameters must be estimated on training data only and applied unchanged to validation and test data. Estimating them on the full dataset introduces information leakage.
- Model Building. Select an algorithm that matches the prediction objective and data structure. Binary outcomes such as brand switching often use logistic regression. Complex multivariate problems with interacting variables often use ensemble methods.
- Training And Validation. Train on historical data and validate on held-out data the model never saw. A model trained on one slice of history and tested on a later time period that scores 0.85 AUC on training data but 0.61 on the holdout has memorized rather than learned.
- Prediction. Generate probability scores for each customer or concept. A score of 0.34 for “purchases within 30 days” means a 34% estimated probability of buying in the next month.
- Application To A Research Decision. Translate scores into targeting, retention, or concept decisions. Prediction scores that sit in a dashboard without connection to a specific commercial action amount to expensive analysis with no return.
Five Common Predictive Analytics Models In Consumer Research
Five model types cover most consumer research prediction problems. Each aligns with a specific outcome type, data structure, and interpretability need.
- Logistic Regression. Best for binary outcomes such as brand switching or churn. Coefficients are directly interpretable as effect sizes under fixed conditions of other variables, so stakeholders can see which inputs drive the score. Logistic regression is recommended for binary outcomes such as brand switching, with random forest and gradient boosting reserved for complex multivariate predictions with interacting variables.
- Decision Trees. Best for segmenting customers by behavioral rules. The branching structure is easy to explain to non-technical stakeholders and maps naturally onto segment-level targeting decisions.
- Random Forests. Best for complex multivariate predictions with interacting variables. A Random Forest classifier applied to telecom customer data achieved a cross-validation accuracy of 85.75% and a mean ROC-AUC of 93.03%, with tenure-to-monthly-charges ratio and contract type identified as the major behavioral determinants. Random forests are more robust to overfitting than single decision trees.
- Gradient Boosting / XGBoost. Often used for purchase-conversion prediction. A systematic benchmark of five classification algorithms on a 7,043-record telecom dataset found that CatBoost, a gradient boosting variant, attained 96.2% accuracy and a ROC-AUC of 0.990, with the operational value coming from calibrating predicted probabilities into risk tiers rather than from raw classification accuracy alone.
- Neural Networks. Best for high-dimensional data such as clickstreams. A hybrid deep neural network combined with XGBoost achieved a Mean Absolute Error of 0.2193 for purchase probability prediction on nearly 500,000 e-commerce transaction records, outperforming the standalone neural network baseline. Neural networks require larger samples and careful validation to avoid overfitting.
Predictive Analytics Applications Mapped To Customer Behavior Decisions
Predictive analytics in customer behavior delivers the most value when the prediction objective is specific and the output connects directly to a decision. Five applications stand out in consumer insights programs.
- Purchase Probability. A model trained on browsing depth, category affinity, and prior purchase recency assigns each customer a probability of buying within a defined window. The research decision is which segment to prioritize for a new product launch or promotional offer.
- Churn Prediction. Behavioral telemetry such as login frequency, feature depth, and support ticket volume predicts which accounts are most likely to cancel. Behavioral models can flag disengagement weeks before it appears in a satisfaction score because usage declines precede stated dissatisfaction. The research decision is which accounts to prioritize for retention outreach.
- Customer Lifetime Value (CLV). Probabilistic CLV models such as the BG/NBD and Pareto/NBD frameworks estimate the present value of future profits from a customer relationship. Conventional CLV models can overestimate marketing elasticity by 20–40% when marketing interventions are treated as exogenous, because firms allocate marketing strategically based on characteristics that also predict purchase behavior.
- Campaign Response. Response propensity models rank customers by likelihood of engaging with a specific message or offer. Discounting the top-scoring decile is expensive because those customers were going to buy anyway, and standard practice of hammering the top and ignoring everyone else produces excellent-looking campaign reports and mediocre incremental revenue.
- Next-Best-Action. Models combine churn risk, CLV, and response propensity to recommend the most valuable intervention for each customer at a given moment. The research decision is how to sequence touchpoints across a customer journey.
See how Listen Labs connects prediction to explanation
Predictive Customer Analytics And The Limits Of Explanation
The most consequential conceptual error in predictive customer analytics is treating a model’s output as an explanation of why something happens. Prediction and explanation require different methods and different standards of evidence.
A concrete consumer research example shows the gap. A churn model trained on login frequency, support ticket volume, and contract tenure can achieve ROC-AUC in the range of roughly 0.91 to 0.95, with a multilayer perceptron reaching 0.95 ± 0.01 and XGBoost 0.91 ± 0.01 in a peer-reviewed telecom benchmark. That result is strong from a predictive standpoint. The model still cannot tell a research team whether customers are churning because of a product gap, a pricing complaint, a relationship breakdown with their account manager, or a competitor’s new offer. A model can predict an outcome well using variables that merely correlate with it, and a variable can be highly important to a model’s predictions precisely because it is a downstream consequence of the outcome or a proxy for an unmeasured cause.
Shmueli et al. (2019) in the European Journal of Marketing warn that a well-fitting model designed in an explanatory context may perform poorly in out-of-sample prediction, and that the coefficient of determination (R²) only assesses in-sample fit and provides no indication of out-of-sample predictive power. The reverse also holds: a model tuned for out-of-sample prediction accuracy is not tuned to reveal causal structure.
Because machine-learning-derived results are based on associations rather than causality, they should be interpreted as hypothesis-generating rather than confirmatory. SHAP values and permutation importance indicate which variables a model prioritized during prediction and reflect model-specific associations. They describe how the model behaves rather than what causes the outcome.
Confusing prediction with explanation is an expensive mistake in consumer research because it pushes teams toward the wrong levers. A churn model that ranks “number of support tickets” as its most important feature does not imply that reducing support tickets will reduce churn. It may indicate that customers who are already disengaging generate more tickets as a symptom of dissatisfaction. Acting on that feature as though it were causal would be a mistake. Strong research programs pair predictive models for targeting with qualitative conversation to uncover cause.
Why Predictive Models Never Reach 100% Accuracy
Six documented failure modes explain why predictive models in consumer research always carry irreducible uncertainty.
- Overfitting. A model captures the idiosyncratic noise in its training data rather than the underlying signal, which produces impressive in-sample accuracy that collapses on new data. The bias-variance decomposition shows expected prediction error equals squared bias plus variance plus irreducible noise, and when model capacity is large relative to sample size, even near-zero training error can be consistent with poor generalization. A model validated only on training data will systematically overstate its own reliability.
- Data Leakage. A feature is included in the model that is only known after the outcome has already occurred. Target leakage, such as including a shipping address update, loyalty points redeemed, or an order confirmation email opened, makes the model score beautifully in testing but collapse in production. The model appears to predict the future while actually reading the past.
- Bias In Training Data. A model trained on partial or unrepresentative data inherits every blind spot in that data. A standard XGBoost model achieved an overall ROC-AUC of 0.85 but performance dropped to 0.71 for a Rural Seniors cohort versus 0.88 for Urban Tech Adopters, demonstrating algorithmic bias from representation disparity in training data. Models then systematically mispredict underrepresented segments, which are often the segments a research program most needs to understand.
- Concept Drift. Consumer behavior shifts over time, and a model trained on historical patterns degrades quietly as the world changes. The average time for a high-performing consumer behavior prediction model to suffer significant concept drift is 3–6 months, requiring continuous retraining. A pricing change, a new competitor, or a cultural shift produces behavior the model has no basis to anticipate.
- Lack Of Interpretability. Complex models such as gradient boosting ensembles and neural networks do not expose their reasoning in human-readable form. Even a model with high predictive accuracy may fail to explain why it classified a case a certain way, leaving analysts unable to judge whether a prediction reflects genuine signal, spurious association, or latent confounding. A risk score alone is not actionable because the right action depends on the cause, which the score does not contain.
- Privacy Constraints. Data minimization requirements under GDPR, CCPA, and sector-specific regulations limit which behavioral signals can be collected, stored, and used in model training. Privacy, data security, and informed consent are critical governance challenges, including the risk of re-identifying individuals within anonymized datasets and the complexity of ensuring users fully comprehend how their data is utilized in automated modeling.
Integrating Predictive Analytics With Qualitative Consumer Research
Qualitative data strengthens predictive workflows and turns scores into explanations that teams can act on with confidence.
Qualitative interview transcripts, sentiment signals, and observed behavioral data play three distinct roles in a predictive workflow. First, they generate the hypotheses that determine which features are worth engineering. A model that includes a “context-switching friction” feature because qualitative interviews surfaced it as a driver of drop-off will outperform a model that relies only on behavioral telemetry. Second, they explain the patterns a model detects. Explanation needs far fewer data points than prediction, and a handful of well-run conversations with flagged accounts will usually explain a pattern that thousands of rows only detected. Third, they validate whether a model’s top features reflect genuine consumer experience or statistical artifacts.
Big data analytics uses unstructured data to provide dynamic approximations of behavioral patterns, and textual content from user-generated sources allows researchers to infer latent preferences with greater predictive accuracy than conventional field data alone. Unstructured user-generated content is often plagued by noise, lack of demographic representativeness, and selection bias. Structured qualitative interviews conducted with screened, verified participants address all three of those limitations.
Human interpretation retains a decisive advantage in three areas. Researchers infer meaning from ambiguity and contradiction, detect emotional subtext that transcripts do not capture, and generate genuinely novel hypotheses about behavior that has no historical precedent in training data. LLM performance is far more variable when themes must be generated rather than applied, particularly in areas requiring interpretation of tone, nuance, or conversational context.
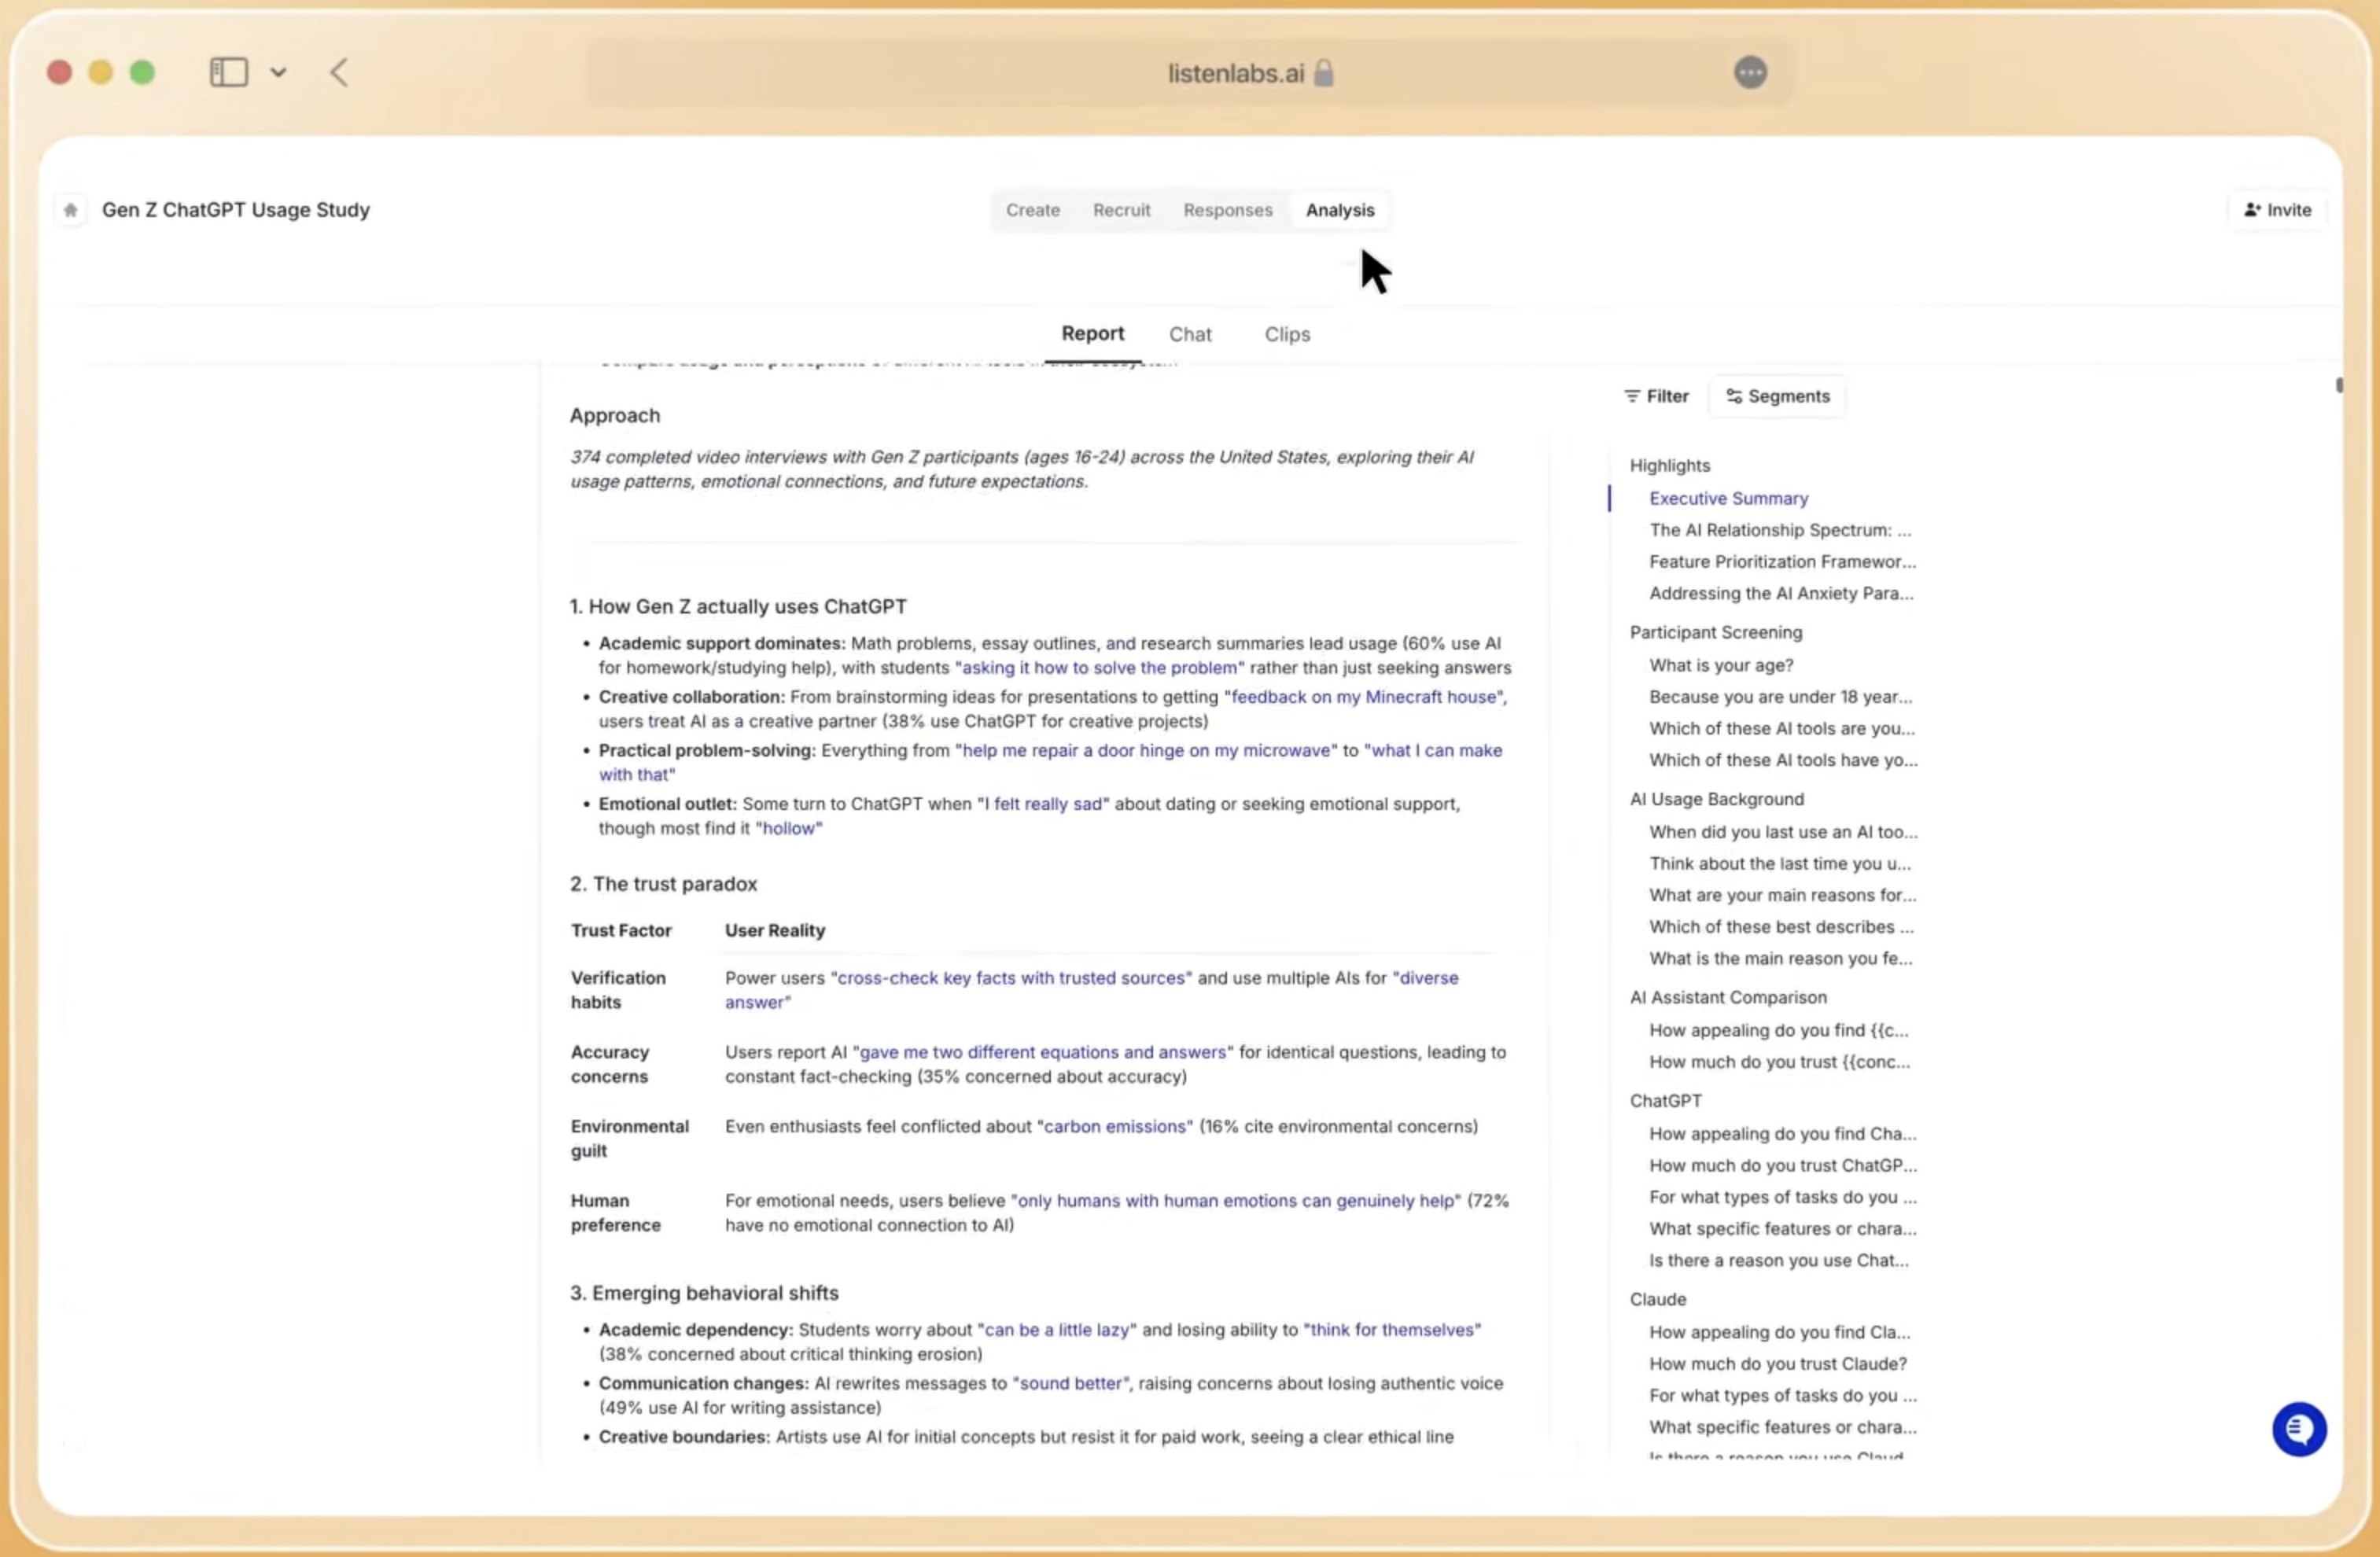
Listen Labs is the end-to-end AI research platform built to connect predictive targeting with qualitative explanation. It sources participants from a 50M+ verified respondent network across 45+ countries and conducts AI-moderated video interviews with dynamic follow-up questions. The resulting behavioral and emotional data feeds directly into predictive modeling workflows and compresses a 4–6 week research cycle into less than 24 hours. Its Emotional Intelligence capability analyzes tone of voice, word choice, and subconscious micro-expressions to quantify emotion per question and concept, built on Ekman’s universal emotions framework. Research teams receive a structured emotional signal that goes beyond what transcripts alone capture. The Research Agent turns interview data into themes, charts, and deliverables through natural-language queries. Listen Labs serves enterprises including Microsoft, Google, Anthropic, P&G, and Skims, and raised a $69M Series B in January 2026.
Predictive Analytics Examples In Consumer Research
Three scenarios show how predictive models connect to real consumer research decisions.
- Concept Selection For A New Product Line. A CPG team has eight packaging concepts and needs to identify which two will drive the highest repeat purchase rate among premium buyers. A MaxDiff exercise typically requires a minimum total sample size of about 300 respondents to generate reliable preference scores, with 200–300 respondents per segment for segment-level analysis and 400–500 or more for individual-level Hierarchical Bayes estimation. A gradient boosting model trained on prior purchase history, category involvement, and demographic signals predicts which concept-segment combinations will convert at the highest rate. The model narrows the field. Qualitative interviews with the top-scoring segment explain why one concept resonates and another does not, surfacing a labeling clarity issue that the scores alone would not have revealed.
- Churn Risk Prioritization For A Subscription Service. A research team builds a random forest model on login frequency, feature adoption depth, and support interaction volume to rank 4,000 accounts by 60-day churn probability. The model flags a subset of accounts as high-risk. Rather than acting on the score alone, the team conducts AI-moderated interviews with 20–30 flagged accounts per at-risk segment, such as 20–30 customers whose CSAT recently declined. The interviews reveal that the primary driver is a workflow integration gap rather than product dissatisfaction, a finding the model detected as a behavioral pattern but could not explain.
- Campaign Response Segmentation. A retail brand tests three creative directions across a nationally representative sample. A logistic regression model trained on prior campaign response data, purchase recency, and category affinity predicts which segment will respond to each creative. Emotional Intelligence analysis of interview responses to each stimulus identifies which creative triggers genuine enthusiasm versus polite approval, a distinction that self-reported ratings alone would have missed.
Frequently Asked Questions
How Does Predictive Analytics Differ From Descriptive Analytics In Consumer Research?
Descriptive analytics summarizes what has already happened, such as average order value last quarter, churn rate by cohort, or NPS trend over 12 months. Predictive analytics uses historical patterns to estimate what is likely to happen next, such as which customers are most likely to churn in the next 60 days, which concept will drive the highest trial rate, or which segment will respond to a campaign. Descriptive analytics answers “what happened,” and predictive analytics answers “what is likely next.” Both are necessary in a mature consumer insights program, because descriptive analytics establishes the baseline and predictive analytics translates that baseline into forward-looking decisions.
What Skills Does A Research Team Need To Run Predictive Models?
A functional predictive analytics capability in a consumer research program requires four skill areas. First, data engineering, which covers assembling, cleaning, and joining behavioral, transactional, and survey data into a modeling-ready dataset. Second, statistical modeling, which includes familiarity with logistic regression, decision trees, random forests, and gradient boosting, along with knowing how to select the right model for a given prediction objective. Third, validation discipline, which includes understanding out-of-sample evaluation, time-based holdout splits, and the difference between in-sample fit and genuine predictive power. Fourth, qualitative interpretation, which covers explaining what a model detects and designing the qualitative research that answers why. Teams that have strong modeling skills but weak qualitative interpretation tend to over-rely on feature importance rankings as causal explanations, which is the most common and most expensive error in applied predictive research.
Can AI Conduct Predictive Analytics?
AI now serves as the primary engine of predictive analytics in consumer research. Machine learning algorithms such as gradient boosting, random forests, and neural networks automate the process of identifying patterns in large datasets and generating probability scores for future outcomes. AutoML platforms further automate feature engineering, algorithm selection, and hyperparameter tuning, which makes predictive modeling accessible to teams without large data science functions. AI still cannot replace the human judgment required to define the right prediction objective, select appropriate training data, validate results against genuine out-of-sample performance, and interpret what the model’s outputs mean for a specific business decision. AI handles the computation, and researchers handle the framing and interpretation.
How Do You Validate A Predictive Model In Consumer Research?
Validation requires evaluating a model on data it never saw during training. The standard approach is to split historical data into a training set, typically 70–80%, and a held-out test set, typically 20–30%. The team trains the model exclusively on the training set and evaluates performance on the test set. For time-series data, which describes most consumer behavior, the split must be temporal, so the model trains on earlier periods and tests on later ones. Random splits that mix time periods allow the model to effectively see the future during training and inflate apparent performance by 20–30%. Beyond accuracy, research teams should evaluate precision at the operating point, recall of actual events, and lift over a naive baseline. A model that cannot beat a simple rule by a clear margin should not be deployed.
How Do Predictive Methods Complement Qualitative Research?
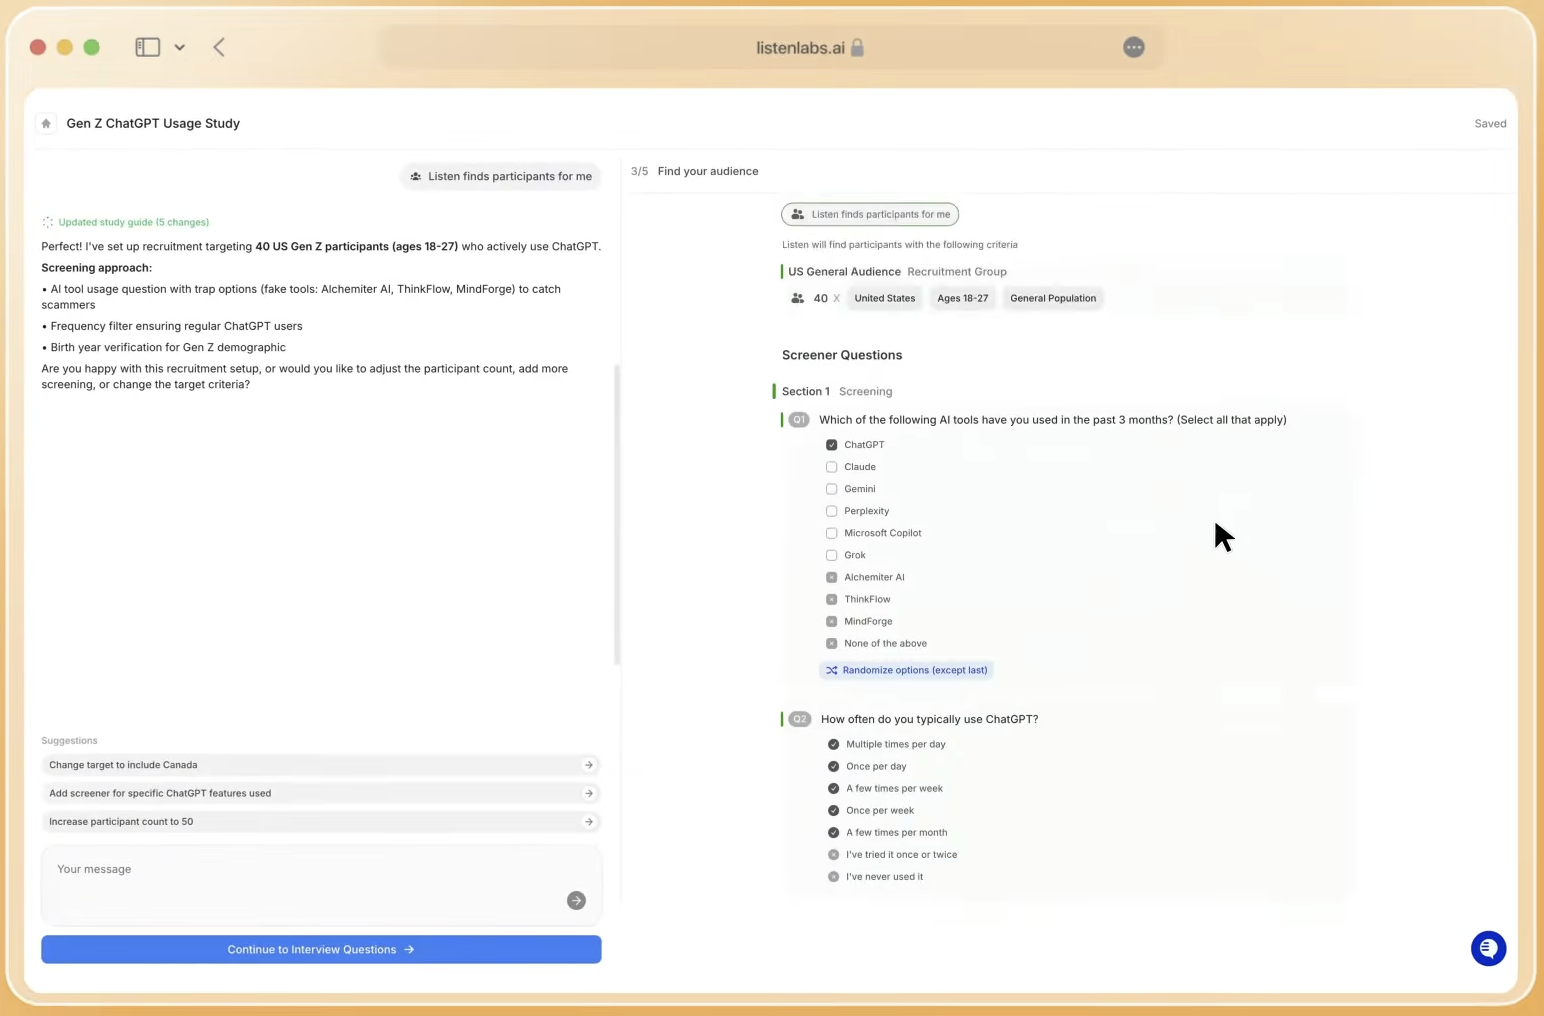
Predictive methods and qualitative research address different questions and become most powerful when used together. Predictive models excel at ranking large populations by risk or propensity, such as identifying which accounts are most likely to cancel, which segment is most likely to trial a new product, or which creative will drive the highest response rate. Qualitative research excels at explaining why those patterns exist by surfacing the motivations, friction points, and emotional drivers that behavioral data can detect but cannot interpret. The productive architecture pairs prediction for targeting with conversation for cause. The model narrows thousands of accounts to the hundreds warranting attention, and researchers then find out why by talking to them. Listen Labs makes this architecture practical by conducting hundreds of AI-moderated qualitative interviews in less than 24 hours and generating structured emotional and behavioral data that feeds back into the predictive workflow.
Conclusion: Pair Prediction With Conversation
Predictive analytics in consumer research functions as a targeting tool rather than an explanation engine. The models covered in this guide, including logistic regression, decision trees, random forests, gradient boosting, and neural networks, are powerful instruments for ranking customers by risk, estimating purchase probability, and forecasting campaign response. They do not reveal why consumers behave as they do, and treating them as explanatory tools produces expensive interventions aimed at the wrong levers.
Strong consumer insights programs treat prediction and explanation as complementary. Predictive models narrow the field, and qualitative interviews explain the pattern. Listen Labs is the end-to-end AI research platform that makes both sides of that architecture work together, using the same capabilities described above to source verified participants, conduct AI-moderated interviews at scale, quantify emotional signals through its Emotional Intelligence capability, and deliver structured data that feeds predictive workflows.
Book a demo to pair prediction with conversation